FP8 (W8A8) quantized version of
Qwen/Qwen3.6-27B by
vrfai using
llm-compressor.
Also available:
vrfai/Qwen3.6-27B-NVFP4 — more aggressive quantization for Blackwell GPUs only.
Same selective strategy as the NVFP4 variant — sensitive components are preserved in BF16:
1# recipe.yaml
2QuantizationModifier:
3  targets: [Linear]
4  scheme: FP8
5  # static W8A8, per-tensor symmetric
6  ignore:
7    - lm_head
8    - re:model\.visual\.blocks\.\d+\..*
9    - model.visual.merger.linear_fc1
10    - model.visual.merger.linear_fc2
11    - re:model\.language_model\.layers\.\d+\.linear_attn\..*
1vllm serve vrfai/Qwen3.6-27B-FP8 \
2  --max-model-len 8192 \
3  --gpu-memory-utilization 0.9 \
4  --dtype auto \
5  --trust-remote-code \
6  --tensor-parallel-size 2
1vllm serve vrfai/Qwen3.6-27B-FP8 \
2  --max-model-len 8192 \
3  --gpu-memory-utilization 0.92 \
4  --dtype auto \
5  --trust-remote-code
The recipes and scripts used to quantize this model can be found in the following repository:
1from transformers import AutoModelForCausalLM, AutoTokenizer
2
3model_name = "vrfai/Qwen3.6-27B-FP8"
4tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
5model = AutoModelForCausalLM.from_pretrained(
6    model_name,
7    torch_dtype="auto",
8    device_map="auto",
9    trust_remote_code=True,
10)
11
12messages = [{"role": "user", "content": "Explain quantization in one paragraph."}]
13text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
14inputs = tokenizer(text, return_tensors="pt").to(model.device)
15outputs = model.generate(**inputs, max_new_tokens=512)
16print(tokenizer.decode(outputs[0][inputs.input_ids.shape[1]:], skip_special_tokens=True))
1from openai import OpenAI
2
3client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
4response = client.chat.completions.create(
5    model="vrfai/Qwen3.6-27B-FP8",
6    messages=[{"role": "user", "content": "Hello!"}],
7    temperature=0.7,
8    max_tokens=512,
9)
10print(response.choices[0].message.content)
1text = tokenizer.apply_chat_template(
2    messages,
3    tokenize=False,
4    add_generation_prompt=True,
5    chat_template_kwargs={"enable_thinking": True},
6)
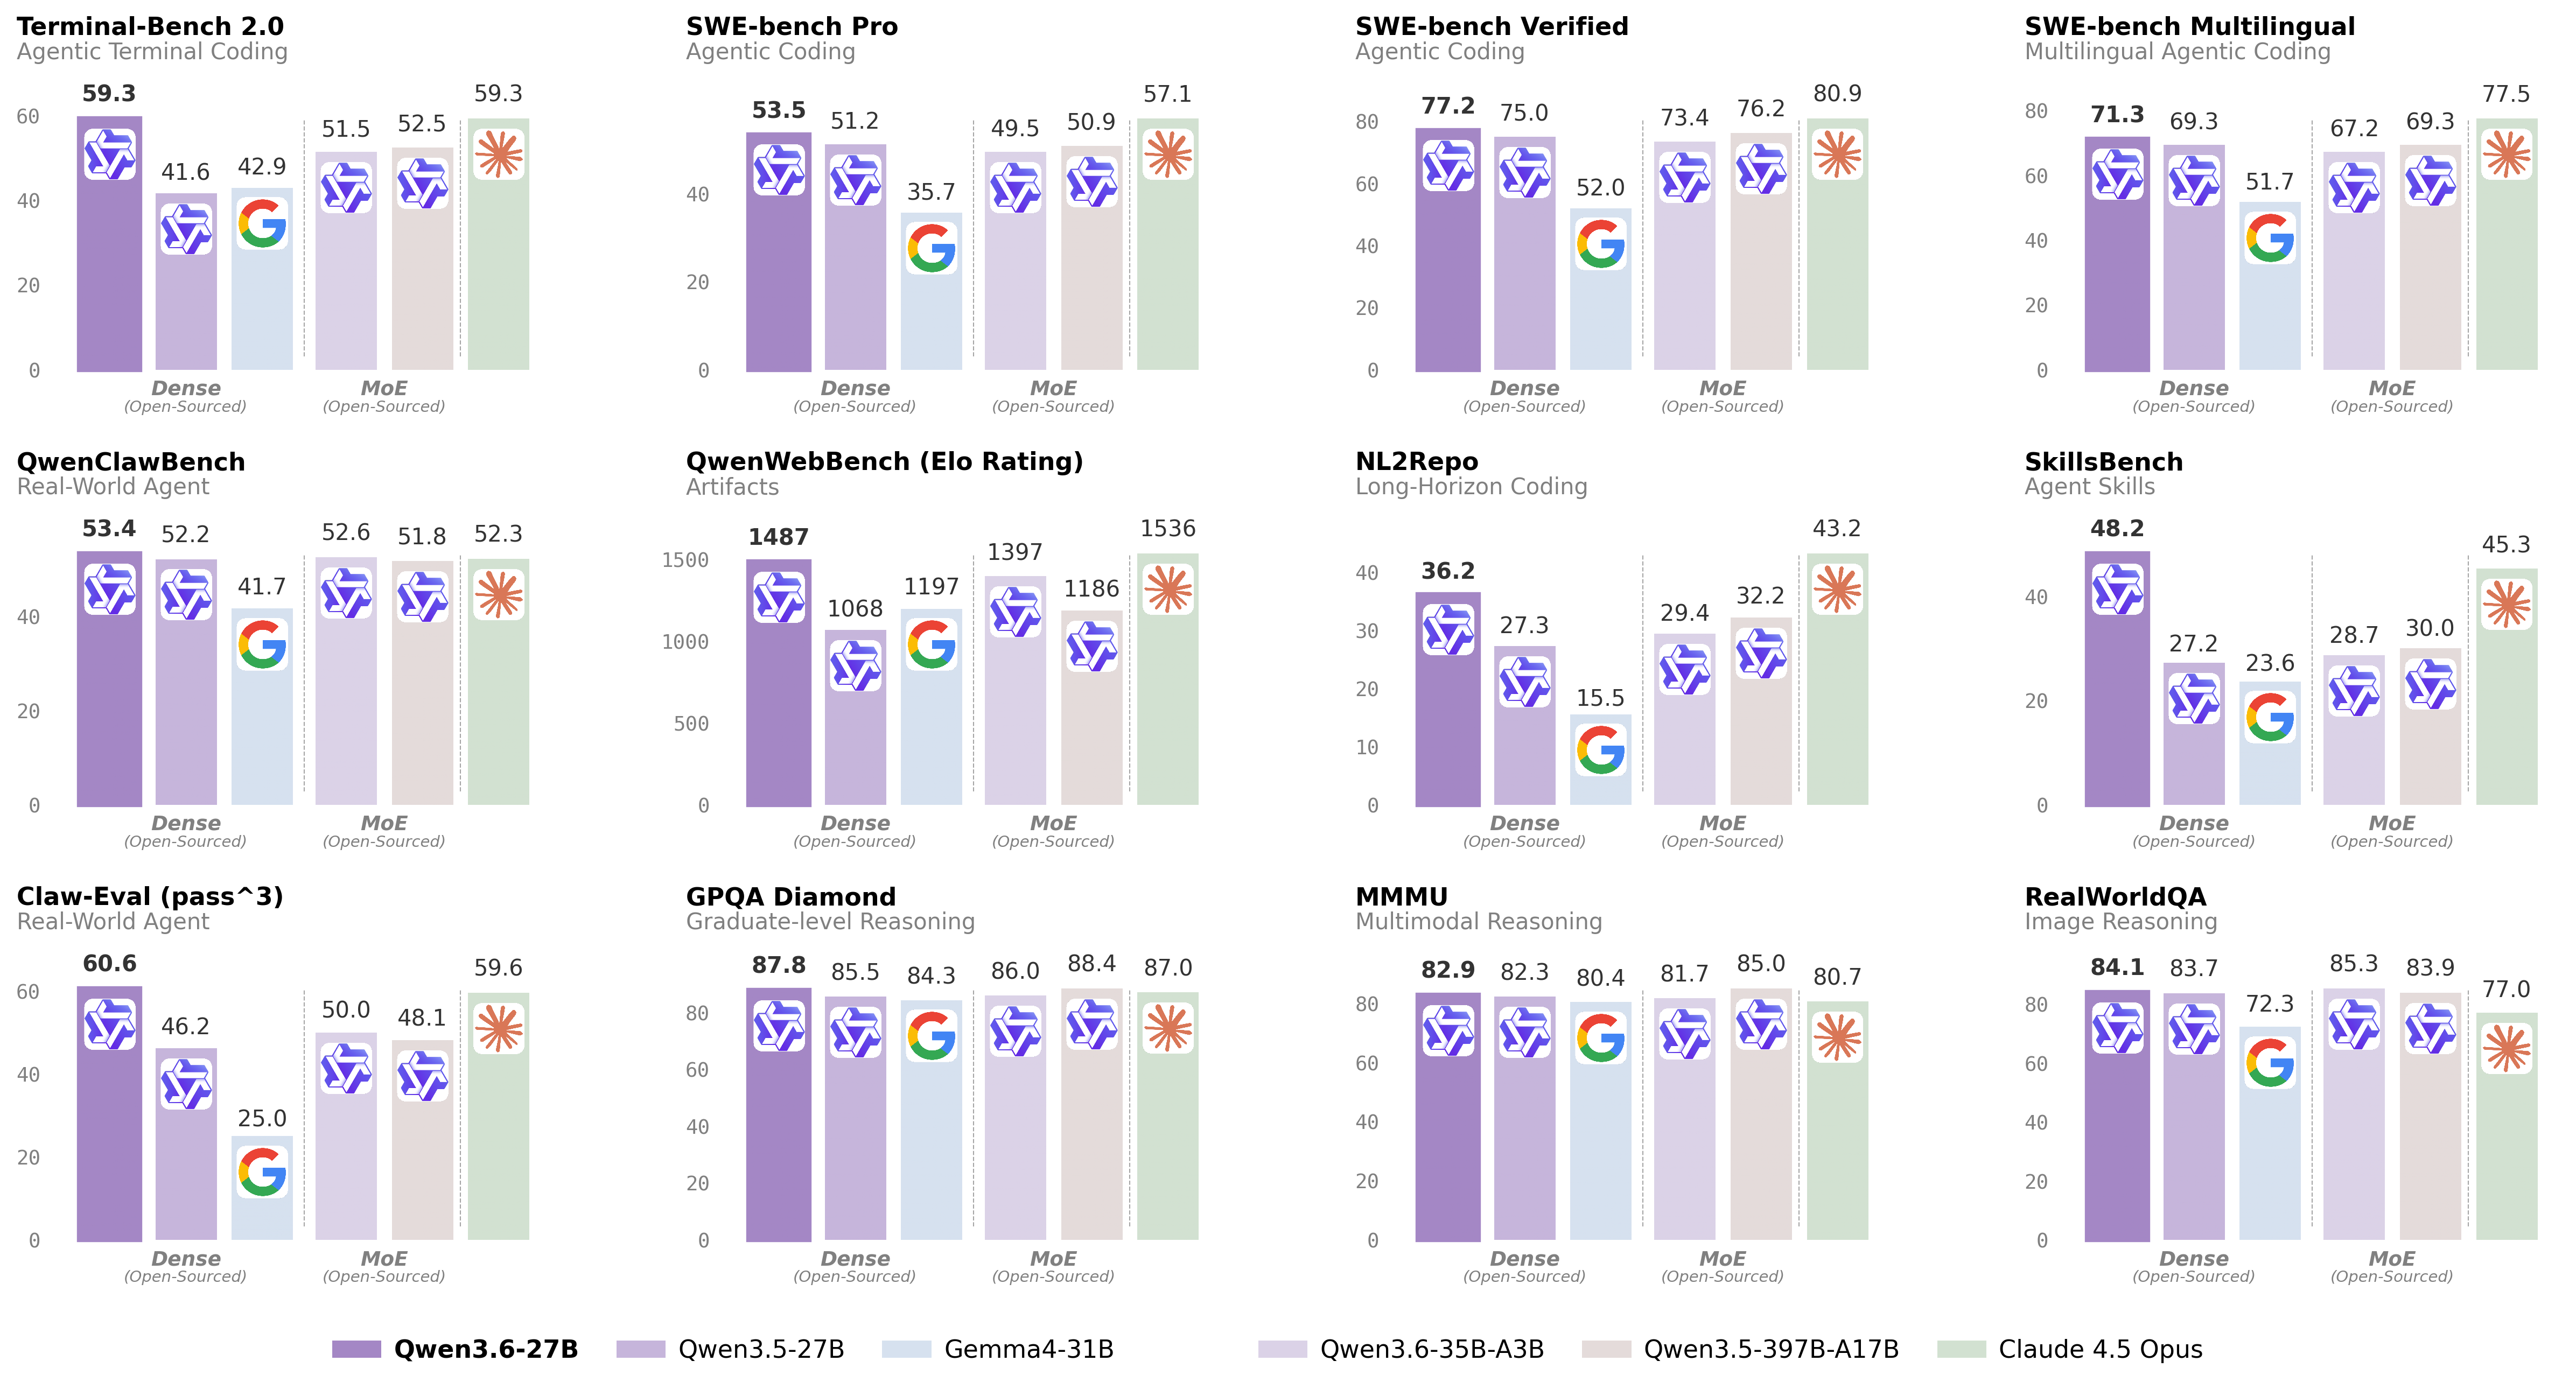
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
For more details, please refer to our blog post
Qwen3.6-27B.
1@misc{qwen3.6-27b,
2    title  = {{Qwen3.6-27B}: Flagship-Level Coding in a {27B} Dense Model},
3    author = {{Qwen Team}},
4    month  = {April},
5    year   = {2026},
6    url    = {https://qwen.ai/blog?id=qwen3.6-27b}
7}