


Views
No views yet
[!IMPORTANT] This version of ColQwen2 should be loaded with thetransformers 🤗release or Sentence Transformers, not withcolpali-engine. It was converted using theconvert_colqwen2_weights_to_hf.pyscript from thevidore/colqwen2-v1.0-mergedcheckpoint.
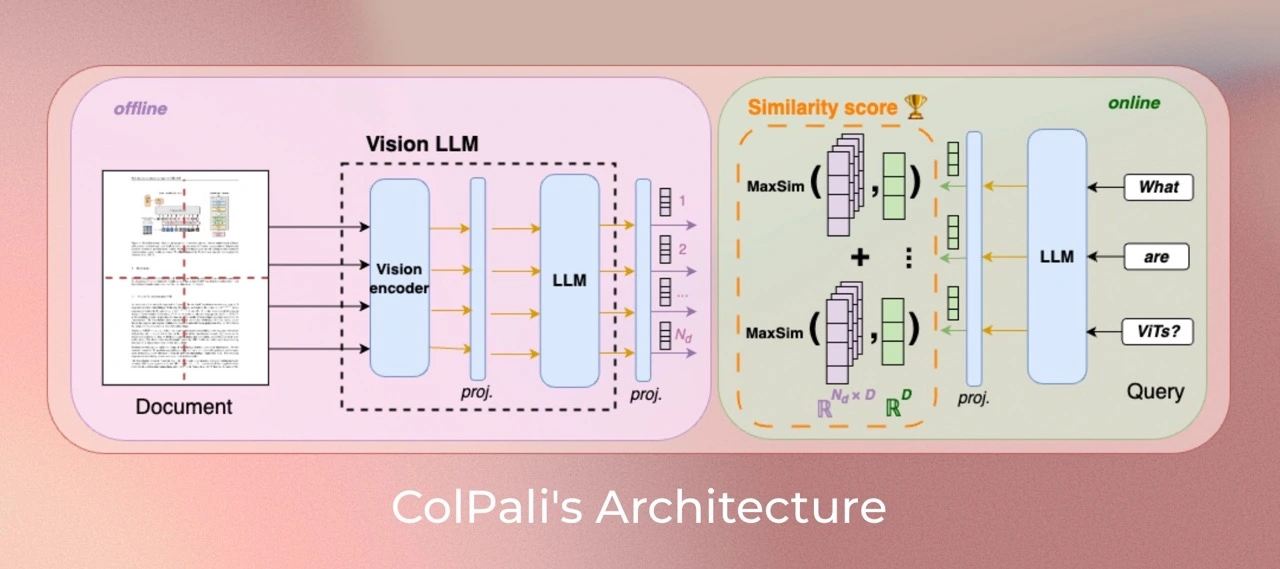
transformers 🤗 implementation was contributed by Tony Wu (@tonywu71) and Yoni Gozlan (@yonigozlan).transformers 🤗 model card: https://huggingface.co/docs/transformers/en/model_doc/colqwen2.MultiVectorEncoder:pip install "sentence-transformers[image]>=6.0.0"1from sentence_transformers import MultiVectorEncoder
2
3model = MultiVectorEncoder("vidore/colqwen2-v1.0-hf")
4
5queries = [
6 "What is the variable represented on the y-axis of the graph?",
7 "Total outlay is maximum in which year?",
8]
9images = [
10 "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc1.jpg",
11 "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc2.jpg",
12 "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc3.jpg",
13 "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc4.jpg",
14]
15
16query_embeddings = model.encode_query(queries)
17document_embeddings = model.encode_document(images)
18print(f"Query 0 shape: {tuple(query_embeddings[0].shape)}")
19print(f"Document 0 shape: {tuple(document_embeddings[0].shape)}")
20# Query 0 shape: (26, 128)
21# Document 0 shape: (755, 128)
22
23# MaxSim late-interaction scoring (rows = queries, columns = images)
24scores = model.similarity(query_embeddings, document_embeddings)
25print(scores)
26# tensor([[14.9668, 11.8184, 12.5811, 11.7061],
27# [ 8.2715, 16.3750, 7.7480, 7.2578]])1import requests
2import torch
3from PIL import Image
4
5from transformers import ColQwen2ForRetrieval, ColQwen2Processor
6from transformers.utils.import_utils import is_flash_attn_2_available
7
8
9# Load the model and the processor
10model_name = "vidore/colqwen2-v1.0-hf"
11
12model = ColQwen2ForRetrieval.from_pretrained(
13 model_name,
14 torch_dtype=torch.bfloat16,
15 device_map="auto", # "cpu", "cuda", or "mps" for Apple Silicon
16 attn_implementation="flash_attention_2" if is_flash_attn_2_available() else "sdpa",
17)
18processor = ColQwen2Processor.from_pretrained(model_name)
19
20# The document page screenshots from your corpus
21url1 = "https://upload.wikimedia.org/wikipedia/commons/8/89/US-original-Declaration-1776.jpg"
22url2 = "https://upload.wikimedia.org/wikipedia/commons/thumb/4/4c/Romeoandjuliet1597.jpg/500px-Romeoandjuliet1597.jpg"
23
24images = [
25 Image.open(requests.get(url1, stream=True).raw),
26 Image.open(requests.get(url2, stream=True).raw),
27]
28
29# The queries you want to retrieve documents for
30queries = [
31 "When was the United States Declaration of Independence proclaimed?",
32 "Who printed the edition of Romeo and Juliet?",
33]
34
35# Process the inputs
36inputs_images = processor(images=images).to(model.device)
37inputs_text = processor(text=queries).to(model.device)
38
39# Forward pass
40with torch.no_grad():
41 image_embeddings = model(**inputs_images).embeddings
42 query_embeddings = model(**inputs_text).embeddings
43
44# Score the queries against the images
45scores = processor.score_retrieval(query_embeddings, image_embeddings)
46
47print("Retrieval scores (query x image):")
48print(scores)1images = [
2 Image.new("RGB", (128, 128), color="white"),
3 Image.new("RGB", (64, 32), color="black"),
4]apache-2.0 license. ColQwen2 inherits from this apache-2.0 license.1@misc{faysse2024colpaliefficientdocumentretrieval,
2 title={ColPali: Efficient Document Retrieval with Vision Language Models},
3 author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
4 year={2024},
5 eprint={2407.01449},
6 archivePrefix={arXiv},
7 primaryClass={cs.IR},
8 url={https://arxiv.org/abs/2407.01449},
9}