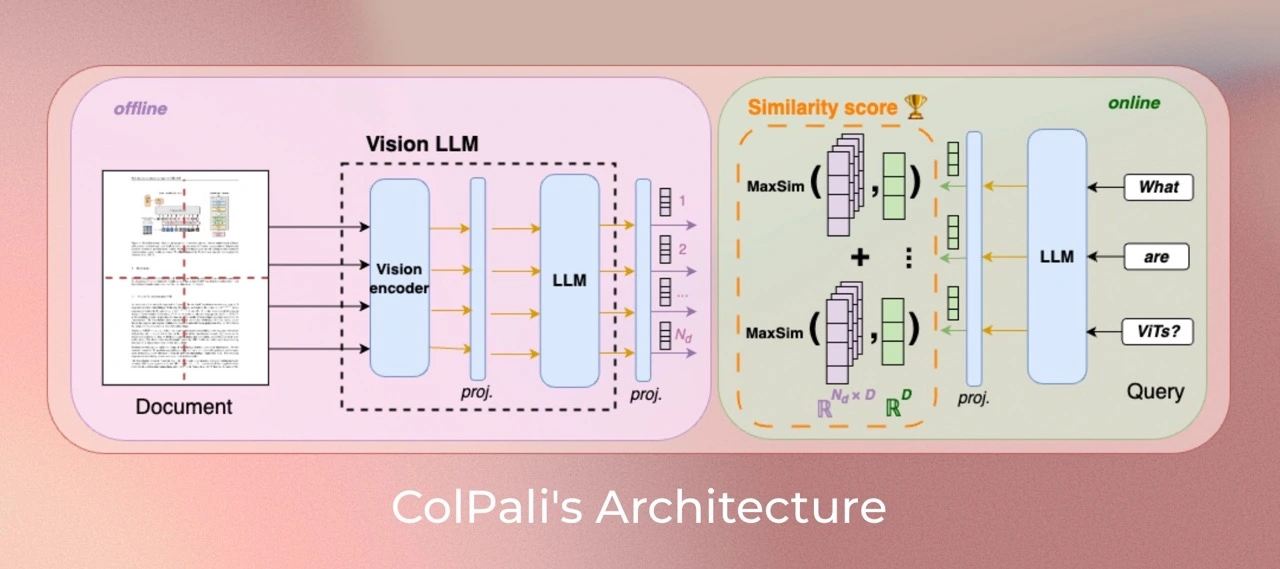
ColPali: Visual Retriever based on PaliGemma-3B with ColBERT strategy
ColPali is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features.
It is a PaliGemma-3B extension that generates ColBERT- style multi-vector representations of text and images.
It was introduced in the paper ColPali: Efficient Document Retrieval with Vision Language Models and first released in this repository
The HuggingFace transformers 🤗 implementation was contributed by Tony Wu (@tonywu71) and Yoni Gozlan (@yonigozlan).
Model Description
This model is built iteratively starting from an off-the-shelf SigLIP model.
We finetuned it to create BiSigLIP and fed the patch-embeddings output by SigLIP to an LLM, PaliGemma-3B to create BiPali.
One benefit of inputting image patch embeddings through a language model is that they are natively mapped to a latent space similar to textual input (query).
This enables leveraging the ColBERT strategy to compute interactions between text tokens and image patches, which enables a step-change improvement in performance compared to BiPali.
Model Training
Dataset
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%).
Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both ViDoRe and in the train set to prevent evaluation contamination.
A validation set is created with 2% of the samples to tune hyperparameters.
Note: Multilingual data is present in the pretraining corpus of the language model (Gemma-2B) and potentially occurs during PaliGemma-3B's multimodal training.
Parameters
All models are trained for 1 epoch on the train set. Unless specified otherwise, we train models in bfloat16 format, use low-rank adapters (LoRA)
with alpha=32 and r=32 on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a paged_adamw_8bit optimizer.
We train on an 8 GPU setup with data parallelism, a learning rate of 5e-5 with linear decay with 2.5% warmup steps, and a batch size of 32.
Usage
Using Sentence Transformers
ColPali can be used as a multi-vector (ColBERT-style late interaction) retriever with Sentence Transformers via the MultiVectorEncoder:
pip install "sentence-transformers[image]>=6.0.0"
python
1from sentence_transformers import MultiVectorEncoder
23model = MultiVectorEncoder("vidore/colpali-v1.2-hf")45queries =[6"What is the variable represented on the y-axis of the graph?",7"Total outlay is maximum in which year?",8]9documents =[10f"https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc{i}.jpg"for i inrange(1,5)11]1213query_embeddings = model.encode_query(queries)14document_embeddings = model.encode_document(documents)15print(f"Query 0 shape: {tuple(query_embeddings[0].shape)}")16print(f"Document 0 shape: {tuple(document_embeddings[0].shape)}")17# Query 0 shape: (23, 128)18# Document 0 shape: (1030, 128)1920# MaxSim late-interaction scoring (rows = queries, columns = images)21scores = model.similarity(query_embeddings, document_embeddings)22print(scores)23# tensor([[11.1816, 10.7031, 8.3398, 5.6191],24# [ 5.5391, 9.4785, 4.7588, 6.1982]])
[!NOTE]
This checkpoint was trained with a five-token <unused0> query augmentation buffer, while
transformers' ColPaliProcessor defaults to ten <pad> tokens (the format later checkpoints use).
The Sentence Transformers configuration restores the original buffer, so its query embeddings match
what this checkpoint was trained on.
Using transformers
python
1import torch
2from PIL import Image
34from transformers import ColPaliForRetrieval, ColPaliProcessor
56model_name ="vidore/colpali-v1.2-hf"78model = ColPaliForRetrieval.from_pretrained(9 model_name,10 torch_dtype=torch.bfloat16,11 device_map="cuda:0",# or "mps" if on Apple Silicon12).eval()1314processor = ColPaliProcessor.from_pretrained(model_name)1516# Your inputs17images =[18 Image.new("RGB",(32,32), color="white"),19 Image.new("RGB",(16,16), color="black"),20]21queries =[22"What is the organizational structure for our R&D department?",23"Can you provide a breakdown of last year’s financial performance?",24]2526# Process the inputs27batch_images = processor(images=images).to(model.device)28batch_queries = processor(text=queries).to(model.device)2930# Forward pass31with torch.no_grad():32 image_embeddings = model(**batch_images)33 query_embeddings = model(**batch_queries)3435# Score the queries against the images36scores = processor.score_retrieval(query_embeddings.embeddings, image_embeddings.embeddings)
The official blog post detailing ColPali can be found here. 📝
The original model implementation code for the ColPali model and for the colpali-engine package can be found here. 🌎
Cookbooks for learning to use the transformers-native version of ColPali, fine-tuning, and similarity maps generation can be found here. 📚
Limitations
Focus: The model primarily focuses on PDF-type documents and high-ressources languages, potentially limiting its generalization to other document types or less represented languages.
Support: The model relies on multi-vector retreiving derived from the ColBERT late interaction mechanism, which may require engineering efforts to adapt to widely used vector retrieval frameworks that lack native multi-vector support.
License
ColPali's vision language backbone model (PaliGemma) is under gemma license as specified in its model card. ColPali inherits from this gemma license.
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
bibtex
1@misc{faysse2024colpaliefficientdocumentretrieval,
2  title={ColPali: Efficient Document Retrieval with Vision Language Models},
3  author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
4  year={2024},
5  eprint={2407.01449},
6  archivePrefix={arXiv},
7  primaryClass={cs.IR},
8  url={https://arxiv.org/abs/2407.01449},
9}