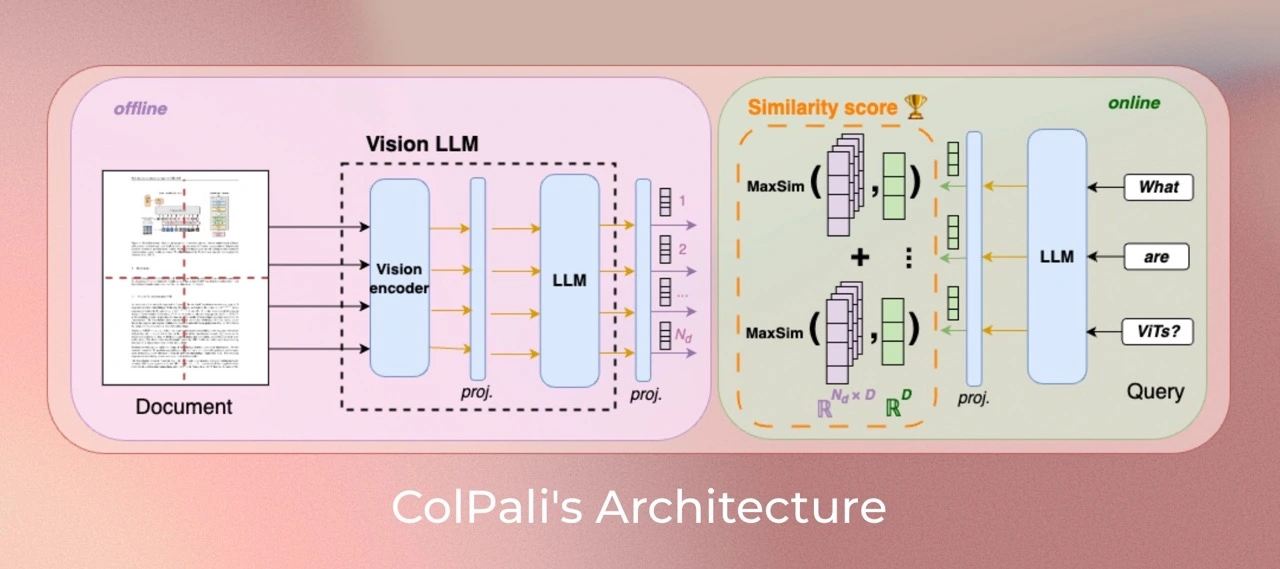
ColSmolVLM is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features.
It is a SmolVLM extension that generates
ColBERT- style multi-vector representations of text and images.
It was introduced in the paper
ColPali: Efficient Document Retrieval with Vision Language Models and first released in
this repositoryThis version is trained with the commit b983e40 of the Colpali repository. (main branch from the repo)
Data is the same as the ColPali data described in the paper.
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%).
Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both ViDoRe and in the train set to prevent evaluation contamination.
A validation set is created with 2% of the samples to tune hyperparameters.
Unless specified otherwise, we train models in
bfloat16 format, use low-rank adapters (
LoRA)
with
alpha=32 and
r=32 on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a
paged_adamw_8bit optimizer.
We train on a 4 GPU setup with data parallelism, a learning rate of 5e-4 with linear decay with 2.5% warmup steps, and a batch size of 8.
ColSmolVLM can be used as a multi-vector (ColBERT-style late interaction) retriever directly with Sentence Transformers via the MultiVectorEncoder:
1from sentence_transformers import MultiVectorEncoder
2
3model = MultiVectorEncoder("vidore/colSmol-256M")
4
5queries = [
6    "What is the variable represented on the y-axis of the graph?",
7    "Total outlay is maximum in which year?",
8]
9images = [
10    "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc1.jpg",
11    "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc2.jpg",
12    "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc3.jpg",
13    "https://huggingface.co/datasets/sentence-transformers/example-documents/resolve/main/doc4.jpg",
14]
15
16query_embeddings = model.encode_query(queries)
17document_embeddings = model.encode_document(images)
18print(f"Query 0 shape:    {tuple(query_embeddings[0].shape)}")
19print(f"Document 0 shape: {tuple(document_embeddings[0].shape)}")
20# Query 0 shape:    (27, 128)
21# Document 0 shape: (1135, 128)
22
23# MaxSim late-interaction scoring (rows = queries, columns = images)
24scores = model.similarity(query_embeddings, document_embeddings)
25print(scores)
26# tensor([[18.1855, 16.2119, 11.7363,  9.7974],
27#         [ 9.2637, 15.1357, 10.4395,  8.0791]])
1import torch
2from PIL import Image
3
4from colpali_engine.models import ColIdefics3, ColIdefics3Processor
5
6model = ColIdefics3.from_pretrained(
7        "vidore/colSmol-256M",
8        torch_dtype=torch.bfloat16,
9        device_map="cuda:0",
10        attn_implementation="flash_attention_2" # or eager
11    ).eval()
12processor = ColIdefics3Processor.from_pretrained("vidore/colSmol-256M")
13
14# Your inputs
15images = [
16    Image.new("RGB", (32, 32), color="white"),
17    Image.new("RGB", (16, 16), color="black"),
18]
19queries = [
20    "Is attention really all you need?",
21    "What is the amount of bananas farmed in Salvador?",
22]
23
24# Process the inputs
25batch_images = processor.process_images(images).to(model.device)
26batch_queries = processor.process_queries(queries).to(model.device)
27
28# Forward pass
29with torch.no_grad():
30    image_embeddings = model(**batch_images)
31    query_embeddings = model(**batch_queries)
32
33scores = processor.score_multi_vector(query_embeddings, image_embeddings)
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
1@misc{faysse2024colpaliefficientdocumentretrieval,
2  title={ColPali: Efficient Document Retrieval with Vision Language Models},
3  author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
4  year={2024},
5  eprint={2407.01449},
6  archivePrefix={arXiv},
7  primaryClass={cs.IR},
8  url={https://arxiv.org/abs/2407.01449},
9}