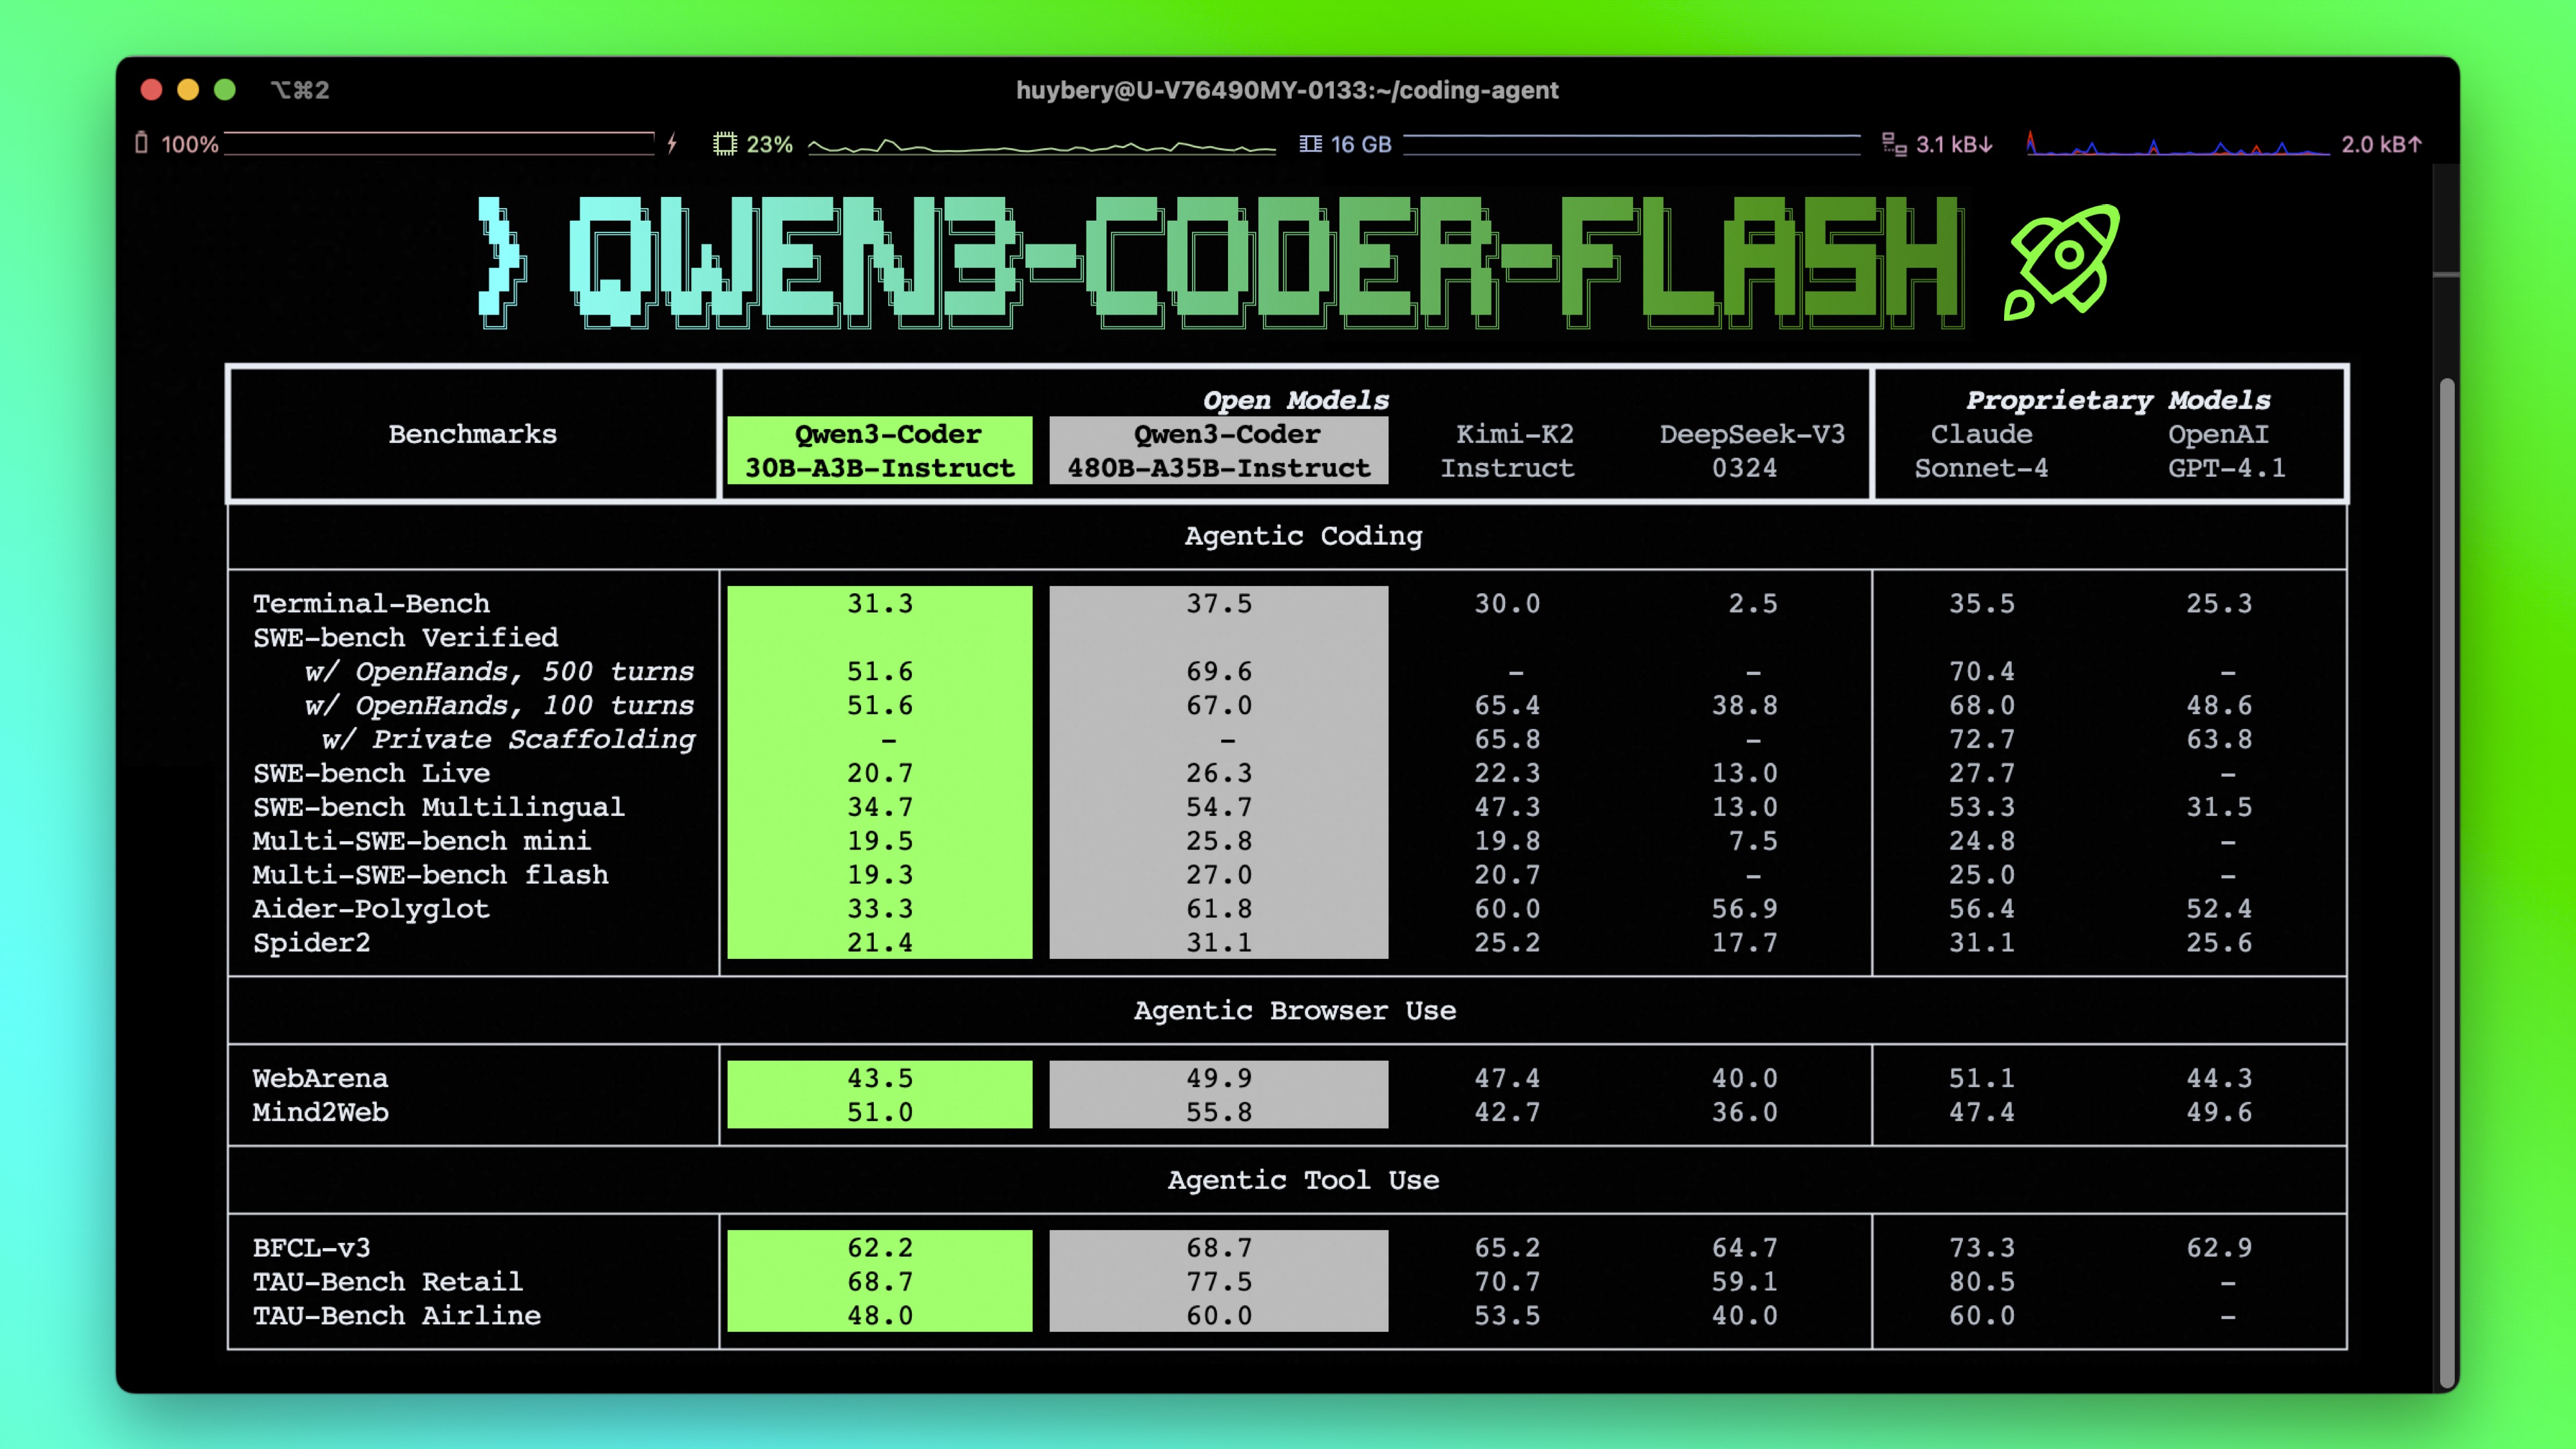
Qwen3-Coder is available in multiple sizes. Today, we're excited to introduce Qwen3-Coder-30B-A3B-Instruct. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
Significant Performance among open models on Agentic Coding, Agentic Browser-Use, and other foundational coding tasks.
Long-context Capabilities with native support for 256K tokens, extendable up to 1M tokens using Yarn, optimized for repository-scale understanding.
Agentic Coding supporting for most platform such as Qwen Code, CLINE, featuring a specially designed function call format.
image/jpeg
Model Overview
Qwen3-Coder-30B-A3B-Instruct has the following features:
Type: Causal Language Models
Training Stage: Pretraining & Post-training
Number of Parameters: 30.5B in total and 3.3B activated
Number of Layers: 48
Number of Attention Heads (GQA): 32 for Q and 4 for KV
Number of Experts: 128
Number of Activated Experts: 8
Context Length: 262,144 natively.
NOTE: This model supports only non-thinking mode and does not generate <think></think> blocks in its output. Meanwhile, specifying enable_thinking=False is no longer required.
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our blog, GitHub, and Documentation.
Quickstart
We advise you to use the latest version of transformers.
With transformers<4.51.0, you will encounter the following error:
KeyError: 'qwen3_moe'
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
python
1from transformers import AutoModelForCausalLM, AutoTokenizer
23model_name ="Qwen/Qwen3-Coder-30B-A3B-Instruct"45# load the tokenizer and the model6tokenizer = AutoTokenizer.from_pretrained(model_name)7model = AutoModelForCausalLM.from_pretrained(8 model_name,9 torch_dtype="auto",10 device_map="auto"11)1213# prepare the model input14prompt ="Write a quick sort algorithm."15messages =[16{"role":"user","content": prompt}17]18text = tokenizer.apply_chat_template(19 messages,20 tokenize=False,21 add_generation_prompt=True,22)23model_inputs = tokenizer([text], return_tensors="pt").to(model.device)2425# conduct text completion26generated_ids = model.generate(27**model_inputs,28 max_new_tokens=6553629)30output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()3132content = tokenizer.decode(output_ids, skip_special_tokens=True)3334print("content:", content)
Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as 32,768.
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
Agentic Coding
Qwen3-Coder excels in tool calling capabilities.
You can simply define or use any tools as following example.
python
1# Your tool implementation2defsquare_the_number(num:float)->dict:3return num **245# Define Tools6tools=[7{8"type":"function",9"function":{10"name":"square_the_number",11"description":"output the square of the number.",12"parameters":{13"type":"object",14"required":["input_num"],15"properties":{16'input_num':{17'type':'number',18'description':'input_num is a number that will be squared'19}20},21}22}23}24]2526import OpenAI
27# Define LLM28client = OpenAI(29# Use a custom endpoint compatible with OpenAI API30 base_url='http://localhost:8000/v1',# api_base31 api_key="EMPTY"32)3334messages =[{'role':'user','content':'square the number 1024'}]3536completion = client.chat.completions.create(37 messages=messages,38 model="Qwen3-Coder-30B-A3B-Instruct",39 max_tokens=65536,40 tools=tools,41)4243print(completion.choice[0])
Best Practices
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
We suggest using temperature=0.7, top_p=0.8, top_k=20, repetition_penalty=1.05.
Adequate Output Length: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
Citation
If you find our work helpful, feel free to give us a cite.