


Views
No views yet
    ██╗    ██╗ █████╗   █████╗  █████╗
    ██║    ██║██╔══██╗ ██╔══██╗██╔══██╗
    ██║ █╗ ██║╚█████╔╝ ███████║╚█████╔╝
    ██║███╗██║██╔══██╗ ██╔══██║██╔══██╗
    ╚███╔███╔╝╚█████╔╝ ██║  ██║╚█████╔╝
     ╚══╝╚══╝  ╚════╝  ╚═╝  ╚═╝ ╚════╝
🗜️ COMPRESSED & OPTIMIZED 🚀1cat Qwen3-Coder-30B-A3B-w8a8-Instruct.py
2from datasets import load_dataset
3from transformers import AutoModelForCausalLM, AutoTokenizer
4
5from llmcompressor.modifiers.quantization import GPTQModifier
6from llmcompressor.modifiers.smoothquant import SmoothQuantModifier
7from llmcompressor.transformers import oneshot
8from llmcompressor.utils import dispatch_for_generation
9from llmcompressor.modifiers.quantization import QuantizationModifier
10# Select model and load it.
11model_id = "Qwen/Qwen3-Coder-30B-A3B-Instruct"
12model = AutoModelForCausalLM.from_pretrained(
13 model_id,
14 torch_dtype="auto",
15 device_map="auto",
16 low_cpu_mem_usage=True,
17 offload_folder="./offload_tmp", # Add offload directory
18 max_memory={0: "22GB", 1: "22GB", "cpu": "64GB"},
19)
20tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
21
22# Select calibration dataset.
23DATASET_ID = "mit-han-lab/pile-val-backup"
24DATASET_SPLIT = "validation"
25
26# Select number of samples. 512 samples is a good place to start.
27# Increasing the number of samples can improve accuracy.
28NUM_CALIBRATION_SAMPLES = 256
29MAX_SEQUENCE_LENGTH = 512
30
31# Load dataset and preprocess.
32ds = load_dataset(DATASET_ID, split=f"{DATASET_SPLIT}[:{NUM_CALIBRATION_SAMPLES}]")
33ds = ds.shuffle(seed=42)
34
35
36def preprocess(example):
37 return {
38 "text": tokenizer.apply_chat_template(
39 [{"role": "user", "content": example["text"]}],
40 tokenize=False,
41 )
42 }
43
44
45ds = ds.map(preprocess)
46
47
48# Tokenize inputs.
49def tokenize(sample):
50 return tokenizer(
51 sample["text"],
52 padding=False,
53 max_length=MAX_SEQUENCE_LENGTH,
54 truncation=True,
55 add_special_tokens=False,
56 )
57
58
59ds = ds.map(tokenize, remove_columns=ds.column_names)
60
61# Configure the quantization algorithm to run.
62# * quantize the activations to int8 (dynamic per token)
63recipe = QuantizationModifier(targets="Linear", scheme="W8A8", ignore=["lm_head", "re:.*mlp.gate$"])
64
65# Apply algorithms.
66oneshot(
67 model=model,
68 dataset=ds,
69 recipe=recipe,
70 max_seq_length=MAX_SEQUENCE_LENGTH,
71 num_calibration_samples=NUM_CALIBRATION_SAMPLES,
72 output_dir="./Qwen/Qwen3-Coder-30B-A3B-Instruct-W8A8", # Add this line
73)
74
75
76# Save to disk compressed.
77SAVE_DIR = model_id.rstrip("/").split("/")[-1] + "-W8A8"
78model.save_pretrained(SAVE_DIR, save_compressed=True)
79tokenizer.save_pretrained(SAVE_DIR)
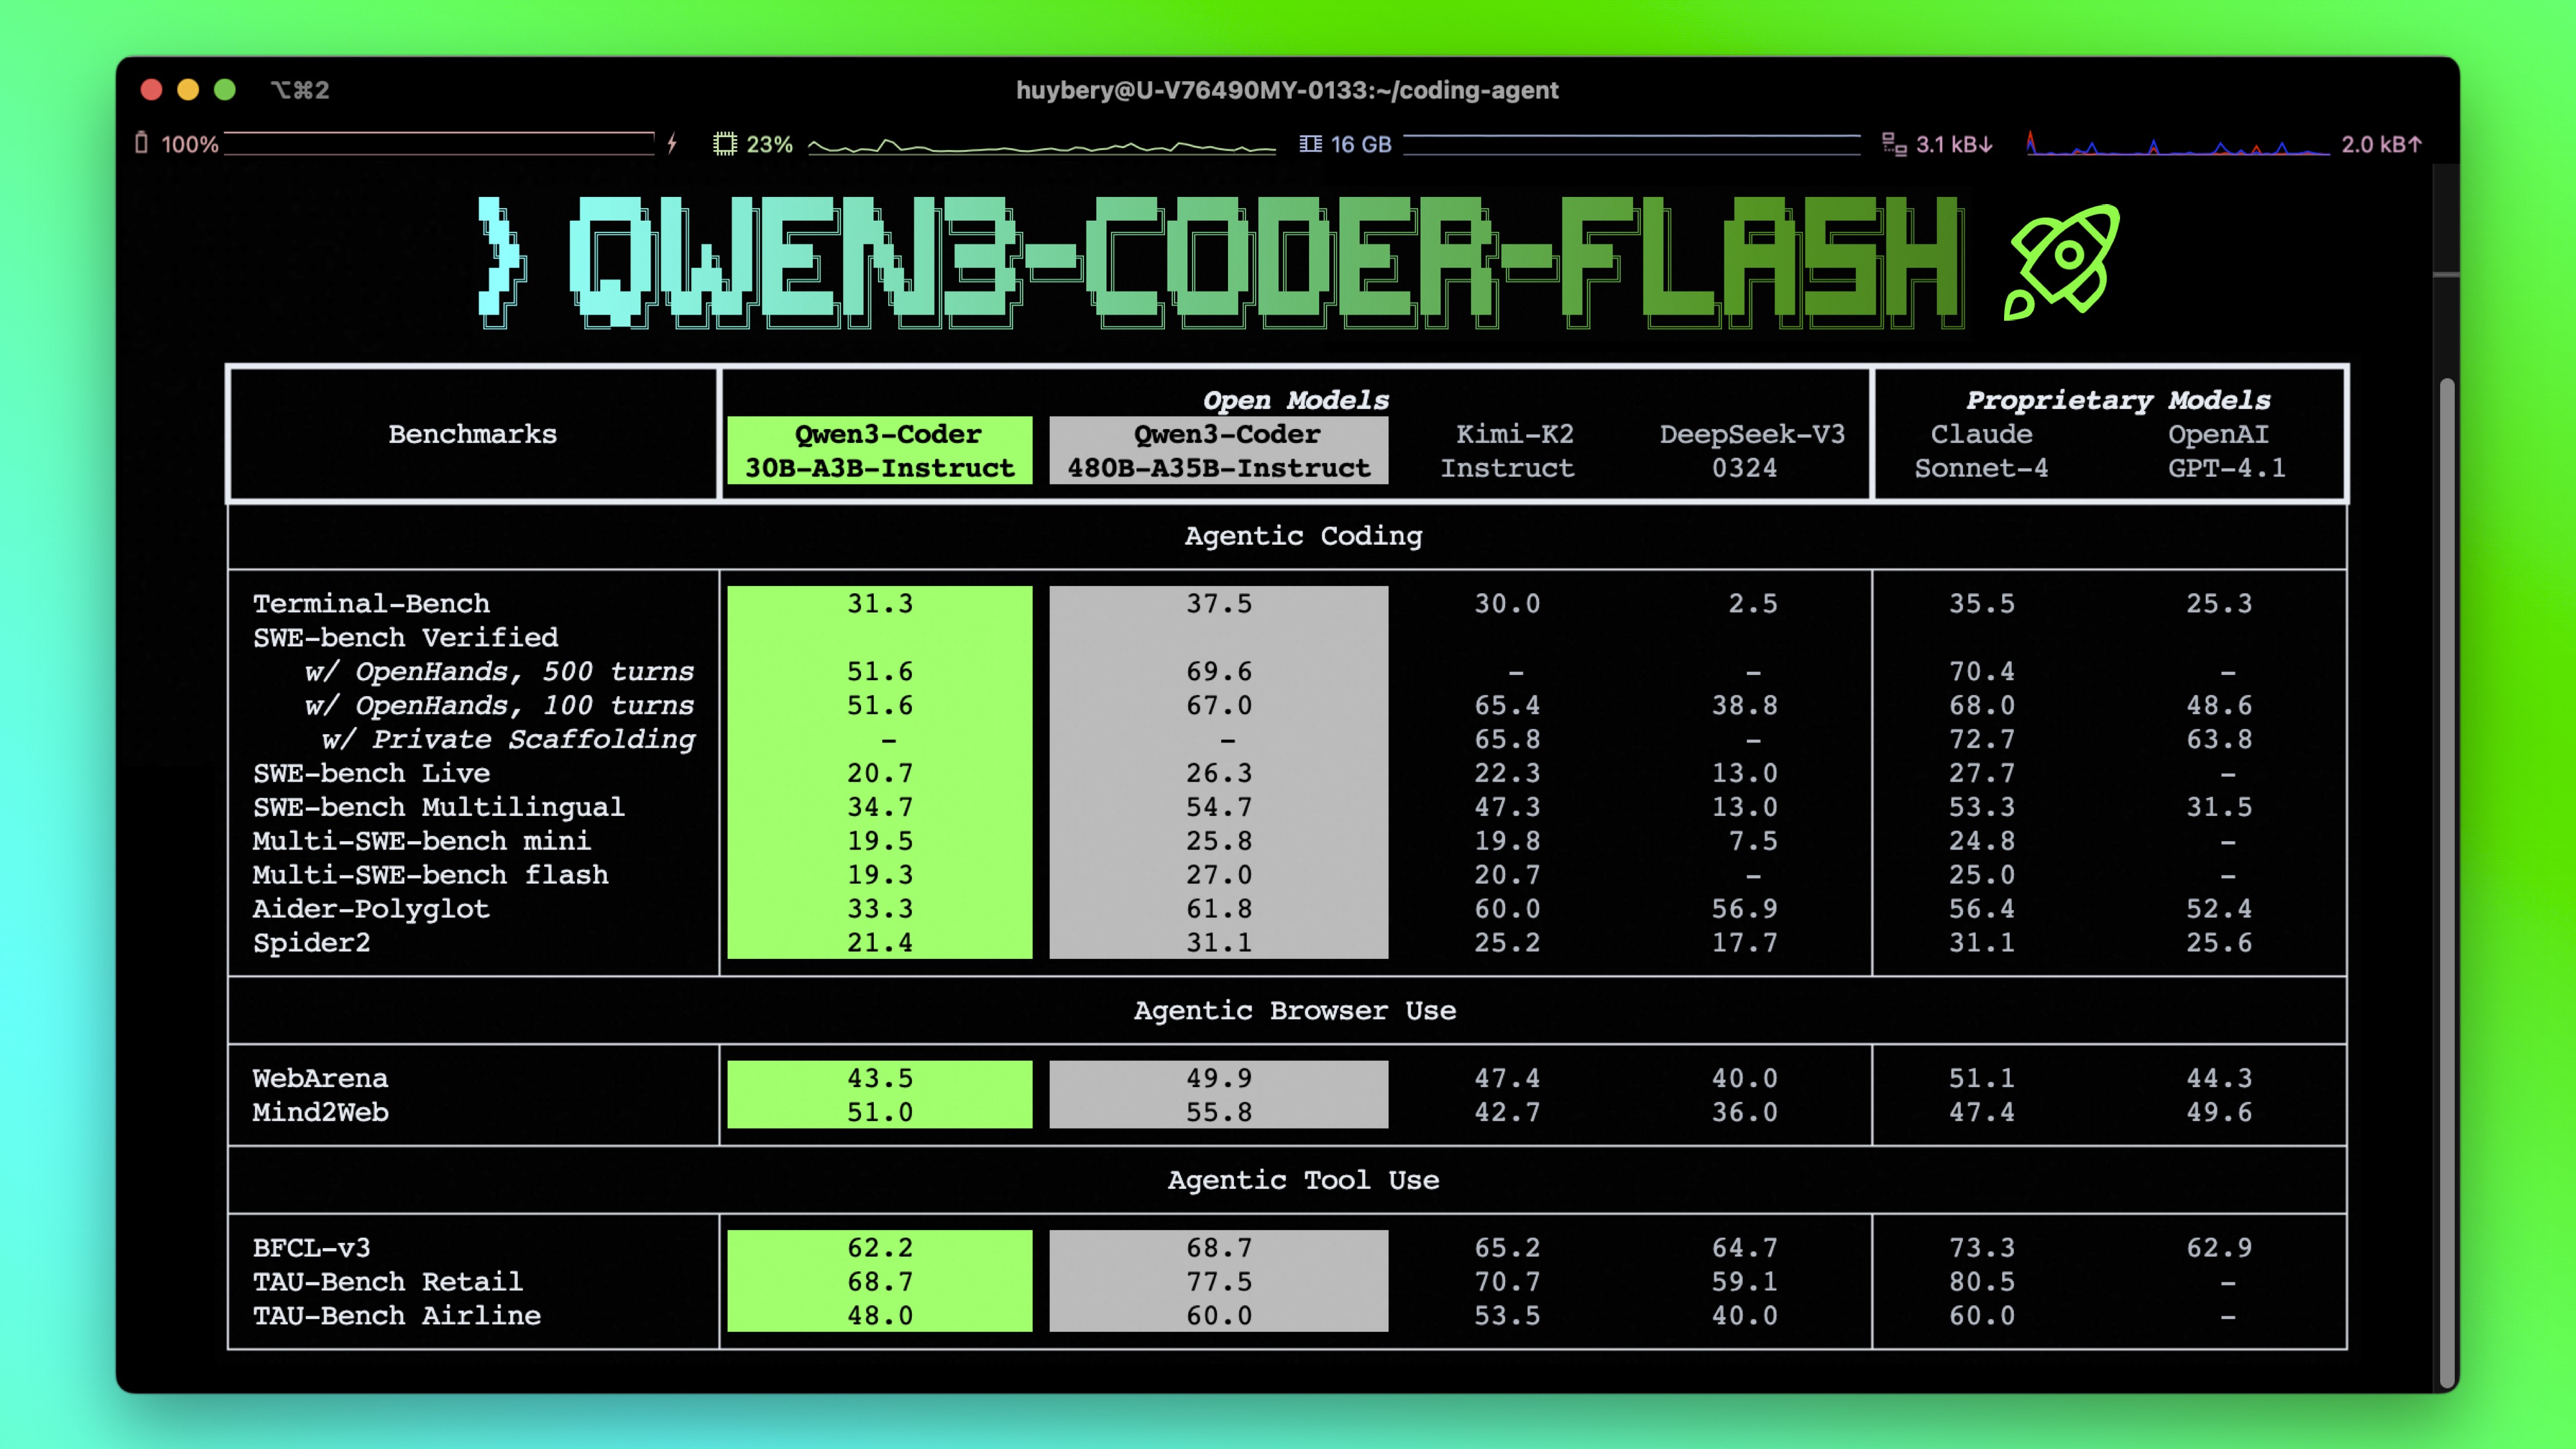
<think></think> blocks in its output. Meanwhile, specifying enable_thinking=False is no longer required.transformers.transformers<4.51.0, you will encounter the following error:KeyError: 'qwen3_moe'1from transformers import AutoModelForCausalLM, AutoTokenizer
2
3model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct"
4
5# load the tokenizer and the model
6tokenizer = AutoTokenizer.from_pretrained(model_name)
7model = AutoModelForCausalLM.from_pretrained(
8 model_name,
9 torch_dtype="auto",
10 device_map="auto"
11)
12
13# prepare the model input
14prompt = "Write a quick sort algorithm."
15messages = [
16 {"role": "user", "content": prompt}
17]
18text = tokenizer.apply_chat_template(
19 messages,
20 tokenize=False,
21 add_generation_prompt=True,
22)
23model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
24
25# conduct text completion
26generated_ids = model.generate(
27 **model_inputs,
28 max_new_tokens=65536
29)
30output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
31
32content = tokenizer.decode(output_ids, skip_special_tokens=True)
33
34print("content:", content)32,768.1# Your tool implementation
2def square_the_number(num: float) -> dict:
3 return num ** 2
4
5# Define Tools
6tools=[
7 {
8 "type":"function",
9 "function":{
10 "name": "square_the_number",
11 "description": "output the square of the number.",
12 "parameters": {
13 "type": "object",
14 "required": ["input_num"],
15 "properties": {
16 'input_num': {
17 'type': 'number',
18 'description': 'input_num is a number that will be squared'
19 }
20 },
21 }
22 }
23 }
24]
25
26import OpenAI
27# Define LLM
28client = OpenAI(
29 # Use a custom endpoint compatible with OpenAI API
30 base_url='http://localhost:8000/v1', # api_base
31 api_key="EMPTY"
32)
33
34messages = [{'role': 'user', 'content': 'square the number 1024'}]
35
36completion = client.chat.completions.create(
37 messages=messages,
38 model="Qwen3-Coder-30B-A3B-Instruct",
39 max_tokens=65536,
40 tools=tools,
41)
42
43print(completion.choice[0])temperature=0.7, top_p=0.8, top_k=20, repetition_penalty=1.05.@misc{qwen3technicalreport,
title={Qwen3 Technical Report},
author={Qwen Team},
year={2025},
eprint={2505.09388},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2505.09388},
}