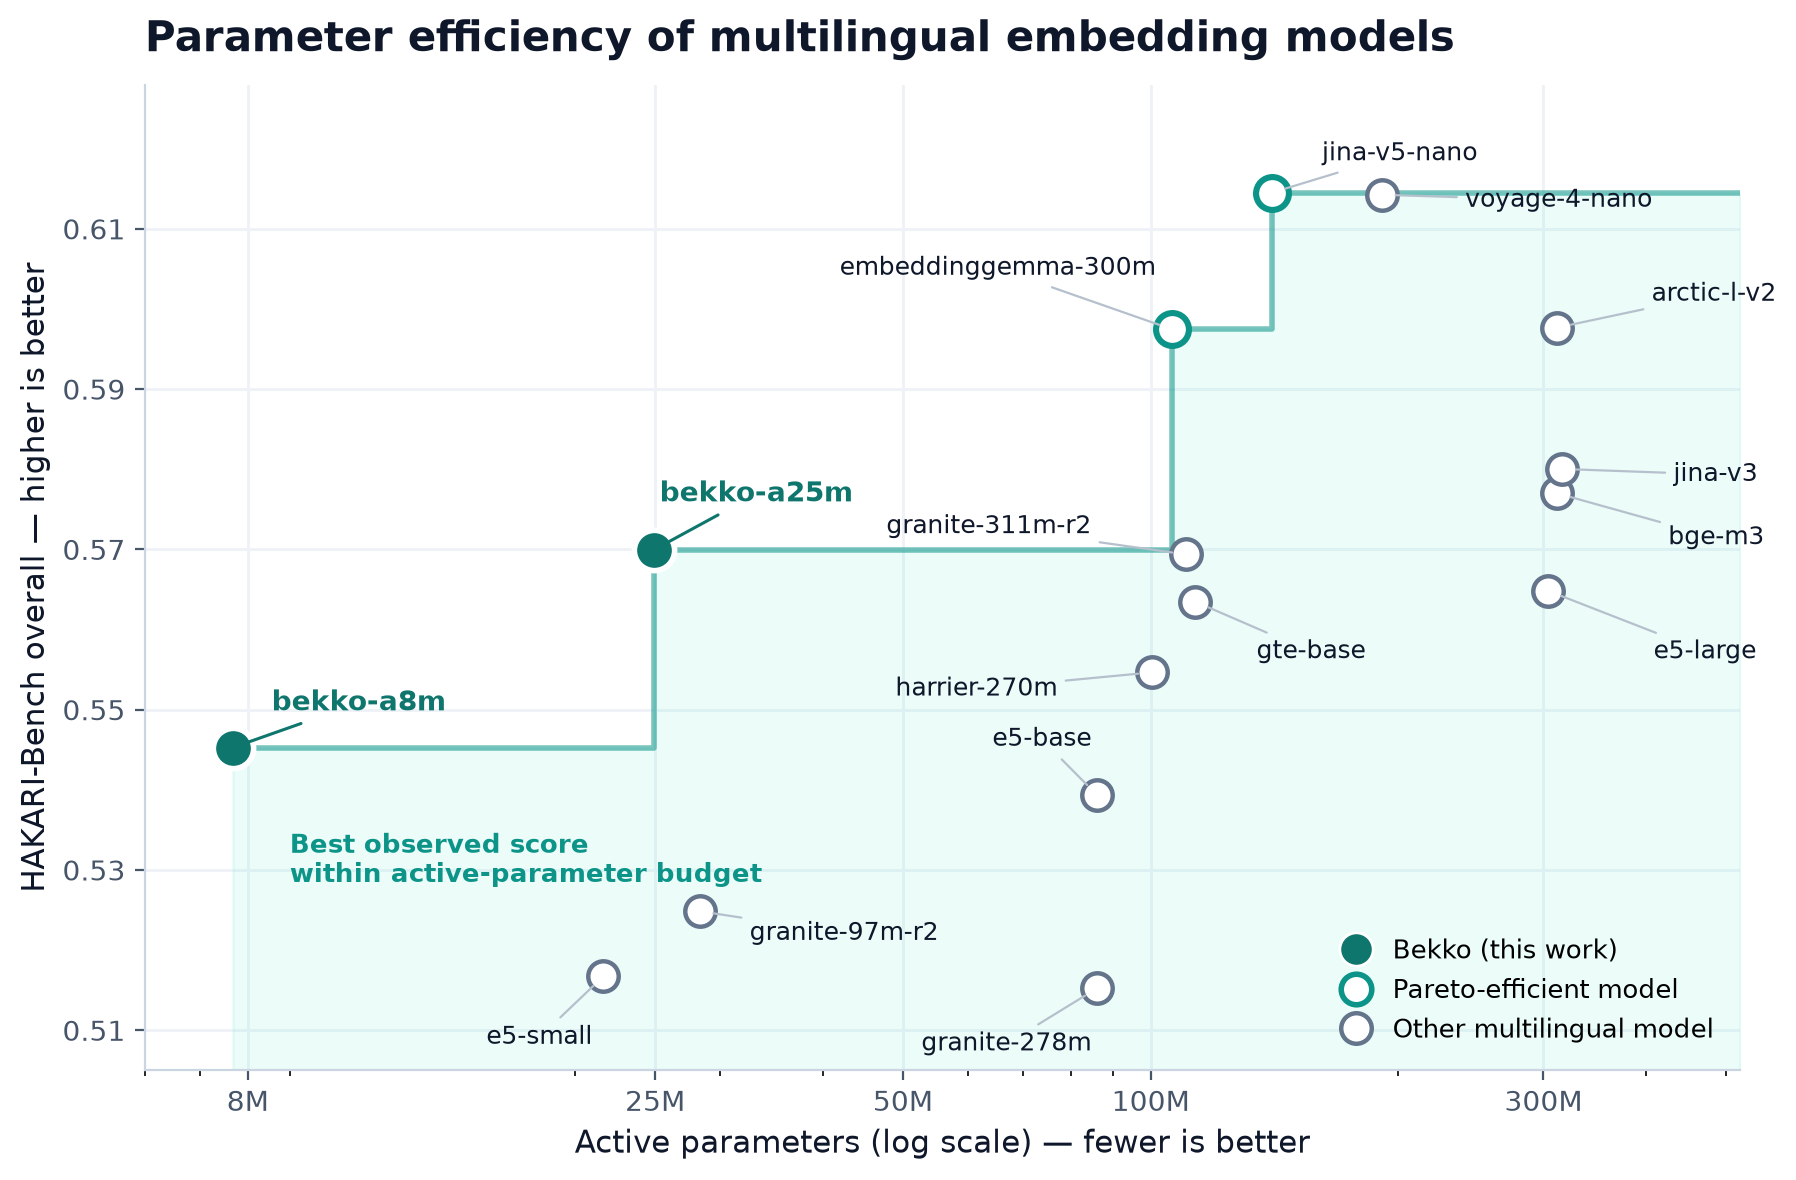
bekko-embedding-v1-a8m is an ultra-compact multilingual text embedding model. It has just 8M active parameters — light enough to run comfortably even on low-spec CPUs — yet its retrieval quality is comparable to models with 3–10x more active parameters.
HAKARI-Bench overall vs active parameters
For higher retrieval quality, see the larger bekko-embedding-v1-a25m (25M active parameters).
You can also try bekko right in your browser: the bekko-embedding-web demo runs the model fully client-side with Transformers.js — no server involved.
[!NOTE]
For a guided overview of the models, training recipe, and results, read Bekko Embedding: how small can a multilingual retrieval model be?.
Highlights
Ultra-compact: just 8M active parameters, with retrieval quality on par with models 3–10x its active-parameter count
100+ languages, context up to 8k tokens
384-dim embeddings that truncate cleanly to 256 / 128 / 64 (Matryoshka)
Runs well on CPU — even a Raspberry Pi 5 — with ONNX and OpenVINO artifacts included
Rule of thumb: a8m is the speed pick — the fastest model we measured on every device. If you can spare about 2.7x CPU throughput, a25m buys a solid quality bump.
Quickstart
We recommend Sentence Transformers 5.0+ and Transformers 5.12+:
Queries and documents go through the same encode() call — no prefixes or task instructions needed. Pass normalize_embeddings=True when you plan to search with cosine similarity or dot product.
On GPU, SDPA works out of the box with PyTorch and CUDA. Flash Attention 2 requires pip install flash-attn --no-build-isolation; on our RTX 5090 it was about 18% faster, and can be enabled by replacing "sdpa" below with "flash_attention_2". Sentence Transformers selects CUDA automatically, so device is normally unnecessary; to force it, use device="cuda", not "gpu".
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5# model_kwargs={"attn_implementation": "sdpa"}, # Optional on GPU6)78query ="What are the characteristics of sushi?"9docs =[10"A warm noodle soup served in broth with sliced toppings.",11"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."12"Une fine crepe garnie de sucre, de beurre ou de fruits.",13"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",14]1516query_emb = model.encode(query, normalize_embeddings=True)17doc_emb = model.encode(docs, normalize_embeddings=True)18scores = util.cos_sim(query_emb, doc_emb)[0]1920print(scores)21print("best doc:", docs[int(scores.argmax())])
Output (exact scores vary slightly by backend):
text
1tensor([0.3085, 0.2716, 0.2750, 0.4738])
2best doc: A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.
Queries and documents don't need to share a language. Continuing with the same model, a Japanese query finds the right English document in a mixed English / Spanish corpus:
python
1corpus =[2"Sushi is a Japanese dish of vinegared rice topped with seafood.",3"The Eiffel Tower is a wrought-iron lattice tower in Paris, France.",4"Mount Fuji is the highest mountain in Japan, at 3,776 meters.",5"Python is a programming language known for its readability.",6"La Sagrada Família es una basílica de Barcelona diseñada por Antoni Gaudí.",7]8corpus_emb = model.encode(corpus, normalize_embeddings=True)910for query in[11"日本で一番高い山は?",# "What is the highest mountain in Japan?"12"Who designed the famous basilica in Barcelona?",13]:14 query_emb = model.encode(query, normalize_embeddings=True)15 hits = util.semantic_search(query_emb, corpus_emb, top_k=2)[0]16print(query)17for hit in hits:18print(f" {hit['score']:.3f}{corpus[hit['corpus_id']]}")
text
1日本で一番高い山は?
2  0.609  Mount Fuji is the highest mountain in Japan, at 3,776 meters.
3  0.219  Sushi is a Japanese dish of vinegared rice topped with seafood.
4Who designed the famous basilica in Barcelona?
5  0.489  La Sagrada Família es una basílica de Barcelona diseñada por Antoni Gaudí.
6  0.152  The Eiffel Tower is a wrought-iron lattice tower in Paris, France.
That's everything you need for basic use. For more speed — OpenVINO on CPU, Flash Attention on GPU, browser inference, smaller embeddings — see Optimized Inference below.
Benchmark results
In the chart above, up and to the left is better: more retrieval quality from fewer active parameters. The step line shows the best observed score within each active-parameter budget, and outlined markers identify Pareto-efficient models. Both bekko models sit in that upper-left region, scoring at or above many models several times their size — which is the whole point of the project.
HAKARI-Bench overall vs active parameters
On the 131-task MMTEB Multilingual v2 suite, a8m scores 56.2 Retrieval and 56.7 Mean(Task) with 7.7M active parameters — a higher Retrieval score than multilingual-e5-small (50.9), multilingual-e5-large (53.7), and BGE-M3 (54.6), all models with 3–40x more active parameters.
MMTEB Multilingual v2 comparison (131 tasks)
Scores are ×100. Retrieval is task-macro nDCG@10, and Mean is the mean across all 131 tasks. Competitor values use the official 2026-06-28 snapshot. Bekko was evaluated over the same task set and aggregation rules.
Model
Active Params
Dims
Mean
Retrieval
Reranking
BitextMining
STS
bekko-embedding-v1-a8m
7.7M
384
56.7
56.2
60.6
73.1
71.6
multilingual-e5-small
21.6M
384
56.4
50.9
60.4
69.4
71.7
bekko-embedding-v1-a25m
24.9M
384
58.3
57.5
61.6
75.4
73.4
granite-embedding-97m-multilingual-r2
28.3M
384
51.9
60.3
59.4
44.2
65.6
harrier-oss-v1-270m
100.3M
640
66.6
66.4
61.9
81.5
75.4
embeddinggemma-300m
106.3M
768
61.2
62.5
63.3
64.4
74.7
granite-embedding-311m-multilingual-r2
110.3M
768
56.0
65.2
62.0
57.9
69.0
gte-multilingual-base
113.3M
768
58.3
57.2
60.7
71.8
72.9
multilingual-e5-large
303.9M
1024
58.6
53.7
62.9
73.8
73.3
snowflake-arctic-embed-l-v2.0
311.8M
1024
57.0
58.4
63.7
64.1
70.1
BGE-M3
311.8M
1024
59.6
54.6
62.8
79.1
74.1
Full MMTEB Retrieval: all 18 tasks and representative models
Scores are ×100. a25m is stronger than a8m on 13 of 18 tasks and on the mean. Its main regression is WinoGrande.
The "a8m" in the name counts active parameters: the attention and feed-forward weights that run on every token, which is where nearly all of a transformer encoder's inference cost lives. The token embedding table dominates the total parameter count, but at inference it's only a lookup.
That's why a model can be large on disk and still fast. bekko-embedding-v1-a8m totals ~106M parameters, but the bulk of that is the multilingual embedding table — only 8M parameters do real work per token, so latency behaves like an 8M model. The default OpenVINO / ONNX artifacts also store that static table as row-wise int8, cutting the main artifact from ~404 MiB fp32 to about 124 MiB.
Speed vs other models
a8m was the fastest model we measured in every environment — x86 CPU, Raspberry Pi 5, Apple Silicon, and NVIDIA GPU. On a Ryzen 9 7950X with OpenVINO it encodes 364 docs/s (1.6x multilingual-e5-small, 17x multilingual-e5-large), and 5,561 docs/s on an RTX 5090 with Flash Attention 2.
Measured throughput and benchmark setup
Document throughput uses Natural Questions text, batch size 64 and max length 512 for CPU/MPS. CUDA uses NQ 100k, fp16, and Flash Attention 2. All throughput values in the table are docs/s.
Model
AP
x86
Pi 5
M4
RTX
bekko-a8m
7.7M
364
33
592
5,561
mE5-small
21.6M
226
19
370
3,746
bekko-a25m
24.9M
134
10.5
351
4,006
granite-97m-r2
28.3M
125
10.0
286
3,917
EmbGemma-300m
106.3M
—
—
97
1,678
granite-311m-r2
110.3M
38
2.9
106
2,159
mE5-large
303.9M
21
1.5
67
1,318
BGE-M3
311.8M
—
—
78
1,324
Abbreviations: mE5 = multilingual-e5, granite-97m/311m-r2 = Granite Embedding Multilingual R2, EmbGemma = EmbeddingGemma. x86 = Ryzen 9 7950X + OpenVINO, Pi 5 = Raspberry Pi 5 + OpenVINO, M4 = Apple M4 Max + MPS, RTX = RTX 5090 + CUDA/Flash Attention 2. AP means active parameters.
Throughput depends on input lengths, batch size, runtime, and hardware. OpenVINO is recommended for CPU, MPS for Apple Silicon, and Flash Attention 2 for supported NVIDIA GPUs.
Optimized Inference
Choose the backend based on where you run the model:
Target
Recommended backend
Why
NVIDIA GPU
SDPA, or Flash Attention 2 for maximum throughput
SDPA works out of the box with PyTorch and CUDA. Flash Attention 2 requires a separate install but was about 18% faster on our RTX 5090.
Apple Silicon
MPS
Uses the Mac GPU through PyTorch.
Native CPU
OpenVINO; ONNX Runtime is not recommended
OpenVINO was about 5.5x faster than ONNX Runtime on a Ryzen 9 7950X and 1.9x faster on a Raspberry Pi 5.
Browser
ONNX with Transformers.js
Runs fully client-side with WebGPU or WASM.
For native CPU inference, we do not recommend ONNX Runtime; use OpenVINO instead. Keep ONNX for browser deployment or environments that specifically require it. The default OpenVINO and ONNX artifacts both compress only the static token embedding table (~404 MiB fp32 down to about 124 MiB) and stayed within cosine similarity 0.9994 of PyTorch in release verification. The transformer-weight qint8 / quint8 files are separate experiments, not defaults.
NVIDIA GPU
SDPA works everywhere and is the safe default. If your GPU supports Flash Attention 2, it's worth enabling: on our RTX 5090 it was about 18% faster than SDPA for a8m (24% for a25m).
python
1import torch
2from sentence_transformers import SentenceTransformer, util
34model = SentenceTransformer(5"hotchpotch/bekko-embedding-v1-a8m",6 device="cuda",7 model_kwargs={8"attn_implementation":"flash_attention_2",9"dtype": torch.float16,10},11)1213query ="What are the characteristics of sushi?"14docs =[15"A warm noodle soup served in broth with sliced toppings.",16"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."17"Une fine crepe garnie de sucre, de beurre ou de fruits.",18"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",19]2021scores = util.cos_sim(22 model.encode(query, normalize_embeddings=True),23 model.encode(docs, normalize_embeddings=True),24)[0]25print(scores)
If Flash Attention 2 is unavailable, use model_kwargs={"attn_implementation": "sdpa"}.
Mac (Apple Silicon)
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5 device="mps",6 model_kwargs={"attn_implementation":"sdpa"},7)89query ="What are the characteristics of sushi?"10docs =[11"A warm noodle soup served in broth with sliced toppings.",12"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."13"Une fine crepe garnie de sucre, de beurre ou de fruits.",14"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",15]1617scores = util.cos_sim(18 model.encode(query, normalize_embeddings=True),19 model.encode(docs, normalize_embeddings=True),20)[0]21print(scores)
OpenVINO CPU — recommended for CPU
The default IR (openvino/openvino_model.xml + .bin) runs on Intel, AMD, and Arm CPUs, Raspberry Pi included. Only the static token embedding table is stored as int8 — the transformer layers stay fp32, so quality is essentially unchanged (cosine similarity ≥ 0.9994 to PyTorch in our release checks).
bash
1# As of 2026-07-28, Transformers 4.x must be specified so that pip resolves2# a compatible OpenVINO dependency stack.3pip install -U \4"sentence-transformers[openvino]>=5.0"\5"transformers>=4.57,<5"
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5 backend="openvino",6 device="cpu",7 model_kwargs={"file_name":"openvino/openvino_model.xml","device":"CPU"},8)910query ="What are the characteristics of sushi?"11docs =[12"A warm noodle soup served in broth with sliced toppings.",13"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."14"Une fine crepe garnie de sucre, de beurre ou de fruits.",15"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",16]1718scores = util.cos_sim(19 model.encode(query, normalize_embeddings=True),20 model.encode(docs, normalize_embeddings=True),21)[0]22print(scores)
ONNX Runtime / Browser — recommended for browser
The default ONNX artifact (onnx/model.onnx) keeps the tokenizer and full vocabulary unchanged and stores only the static token embedding table as int8. Use it with Transformers.js in the browser, or with ONNX Runtime. If plain CPU throughput is what you're after, OpenVINO above is faster. For a complete client-side example, see the bekko-embedding-web Space.
npm install @huggingface/transformers
js
1import{ pipeline }from"@huggingface/transformers";23// Browser: use WebGPU when available, otherwise fall back to WASM.4// Node.js: replace this line with `const device = "cpu";`.5const device =navigator.gpu?"webgpu":"wasm";67const extractor =awaitpipeline(8"feature-extraction",9"hotchpotch/bekko-embedding-v1-a8m",10{11 device,12// Transformers.js maps dtype="fp32" to onnx/model.onnx.13// In this repo, that file is the compact static-embedding-int8 ONNX model.14dtype:"fp32",15},16);1718const queryEmbedding =awaitextractor("What are the characteristics of sushi?",{19pooling:"mean",20normalize:true,21});2223const documentEmbedding =awaitextractor(24"A Japanese dish made with vinegared rice and seafood.",25{pooling:"mean",normalize:true},26);2728console.log(queryEmbedding.tolist()[0].slice(0,8));29console.log(documentEmbedding.tolist()[0].slice(0,8));30console.log(queryEmbedding.dims);// [1, 384]
pip install -U "sentence-transformers[onnx]>=5.0"
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5 backend="onnx",6 device="cpu",7 model_kwargs={"file_name":"onnx/model.onnx","provider":"CPUExecutionProvider"},8)910query ="What are the characteristics of sushi?"11docs =[12"A warm noodle soup served in broth with sliced toppings.",13"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."14"Une fine crepe garnie de sucre, de beurre ou de fruits.",15"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",16]17print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
Smaller embeddings with Matryoshka (truncate_dim)
These models are trained with Matryoshka representation learning, so you can shrink the 384-dim embeddings to 256, 128, or 64 dimensions by passing truncate_dim. Smaller dimensions reduce index size and speed up similarity search, at a small cost in retrieval quality (see Truncation and Quantization).
python
1from sentence_transformers import SentenceTransformer, util
23# Full embedding is 384-dim; 256 / 128 / 64 are supported.4model = SentenceTransformer(5"hotchpotch/bekko-embedding-v1-a8m",6 truncate_dim=256,7 model_kwargs={"attn_implementation":"sdpa"},8)910query ="What are the characteristics of sushi?"11docs =[12"A warm noodle soup served in broth with sliced toppings.",13"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."14"Une fine crepe garnie de sucre, de beurre ou de fruits.",15"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",16]17emb = model.encode(query, normalize_embeddings=True)18print("embedding dim:", emb.shape[-1])19print(util.cos_sim(emb, model.encode(docs, normalize_embeddings=True))[0])
OpenVINO qint8 (not recommended)
Not the same as the default artifact above — this one quantizes the transformer weights too. We keep it for experimentation only: on models this small, qint8 tends to hurt retrieval quality without reliably improving latency.
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5 backend="openvino",6 device="cpu",7 model_kwargs={"file_name":"openvino/openvino_model_qint8_not_recommended.xml","device":"CPU"},8)910query ="What are the characteristics of sushi?"11docs =[12"A warm noodle soup served in broth with sliced toppings.",13"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."14"Une fine crepe garnie de sucre, de beurre ou de fruits.",15"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",16]17print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
ONNX qint8 / quint8 (not recommended)
Same caveat as OpenVINO qint8: these files quantize the transformer weights and are platform-specific experiments. On models this small they can noticeably degrade retrieval quality, so measure on your target hardware before adopting them.
pip install -U "sentence-transformers[onnx]>=5.0"
python
1from sentence_transformers import SentenceTransformer, util
23model = SentenceTransformer(4"hotchpotch/bekko-embedding-v1-a8m",5 backend="onnx",6 device="cpu",7 model_kwargs={8"file_name":"onnx/model_qint8_avx512_not_recommended.onnx",9"provider":"CPUExecutionProvider",10},11)1213query ="What are the characteristics of sushi?"14docs =[15"A warm noodle soup served in broth with sliced toppings.",16"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."17"Une fine crepe garnie de sucre, de beurre ou de fruits.",18"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",19]20print(util.cos_sim(model.encode(query, normalize_embeddings=True), model.encode(docs, normalize_embeddings=True))[0])
llama.cpp / Ollama / GGUF
For portable inference with llama.cpp or Ollama, use the GGUF release in
bekko-embedding-v1-a8m-GGUF.
The GGUF model uses the same 8192-token context, mean pooling, and
384-dimensional L2-normalized embeddings as this model.
Use BF16 on GPUs and Apple Silicon. For CPU inference, use Q8_0; it is smaller
and avoids the severe BF16 slowdown on CPUs without native BF16 arithmetic.
With llama.cpp:
bash
1llama-server \2 -hf hotchpotch/bekko-embedding-v1-a8m-GGUF:BF16 \3 --embedding --pooling mean --embd-normalize 2 --ctx-size 819245curl http://localhost:8080/v1/embeddings \6 -H 'Content-Type: application/json'\7 -d '{"model":"bekko","input":"What is the tallest mountain in Japan?"}'
With Ollama:
bash
1# Default (BF16): recommended for GPU and Apple Silicon2ollama pull hotchpotch/bekko-embedding-v1-a8m
34curl http://localhost:11434/api/embed \5 -d '{"model":"hotchpotch/bekko-embedding-v1-a8m","input":"What is the tallest mountain in Japan?"}'67# Q8_0: recommended for CPU inference8ollama pull hotchpotch/bekko-embedding-v1-a8m:q8_0
Ollama also provides explicit :bf16 and :f16 tags. The Hugging Face GGUF
repository publishes BF16, F16, and Q8_0. Lower-bit variants are not published
because they provided little file-size reduction for this architecture while
reducing embedding fidelity or throughput. See the GGUF model card for the
measurements and conversion details.
Other inference methods
Beyond the Sentence Transformers backends above, you can also serve or run the model with:
Text Embeddings Inference (production API)
Text Embeddings Inference (TEI) is Hugging Face's Rust-based serving stack, with official Docker images, dynamic batching, and Prometheus metrics built in.
Before deploying, confirm your TEI version supports this model's encoder architecture, and pick the image tag that matches your target — a CPU image, or a GPU image for your specific architecture. See the TEI image list for current tags.
bash
1model=hotchpotch/bekko-embedding-v1-a8m
2volume=$PWD/tei-data
3# Replace <tag> with the current TEI image for your hardware (CPU, or your GPU arch).4# Add `--gpus all` when using a GPU image.5docker run -p 8080:80 -v "$volume:/data" --pull always \6 ghcr.io/huggingface/text-embeddings-inference:<tag>\7 --model-id "$model"
python
1import requests
2import numpy as np
34query ="What are the characteristics of sushi?"5docs =[6"A warm noodle soup served in broth with sliced toppings.",7"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."8"Une fine crepe garnie de sucre, de beurre ou de fruits.",9"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",10]1112q = np.array(requests.post("http://127.0.0.1:8080/embed", json={"inputs":[query]}).json()[0])13d = np.array(requests.post("http://127.0.0.1:8080/embed", json={"inputs": docs}).json())14q = q / np.linalg.norm(q)15d = d / np.linalg.norm(d, axis=1, keepdims=True)16print(d @ q)
Transformers library
Apply mean pooling with pure Transformers.
python
1import torch
2import torch.nn.functional as F
3from transformers import AutoModel, AutoTokenizer
45model_id ="hotchpotch/bekko-embedding-v1-a8m"6tokenizer = AutoTokenizer.from_pretrained(model_id)7model = AutoModel.from_pretrained(model_id, attn_implementation="sdpa").eval()89defembed(texts):10 batch = tokenizer(texts, padding=True, truncation=True, return_tensors="pt")11with torch.no_grad():12 out = model(**batch).last_hidden_state
13 mask = batch["attention_mask"].unsqueeze(-1)14 pooled =(out * mask).sum(dim=1)/ mask.sum(dim=1).clamp(min=1)15return F.normalize(pooled, p=2, dim=1)1617query ="What are the characteristics of sushi?"18docs =[19"A warm noodle soup served in broth with sliced toppings.",20"天ぷらは魚や野菜に衣をつけて揚げた料理です。",# "Tempura is battered, deep-fried fish and vegetables."21"Une fine crepe garnie de sucre, de beurre ou de fruits.",22"A Japanese dish made with vinegared rice, often shaped with seafood, vegetables, or egg.",23]2425scores = embed(docs) @ embed([query]).T
26print(scores.squeeze(-1))
Truncation and Quantization
How much quality do you trade for a smaller index? For bekko-embedding-v1-a8m: very little at 256 dimensions (-1.8%), progressively more below that. If you quantize the output vectors to int8 or binary, add a rescoring step — it recovers nearly all of the loss.
Truncation and output-vector quantization results
Setting
Dim
Encoding
Rescore
HAKARI overall
Delta vs 384-dim float
Recommended use
Full quality
384
float
No
0.545
-
Default choice
Smaller index
256
float
No
0.536
-1.76%
Good size/quality tradeoff
Compact index
128
float
No
0.507
-7.05%
Memory-constrained indexes
Very compact index
64
float
No
0.450
-17.51%
Not for quality-sensitive retrieval
INT8 search
384
int8
No
0.515
-5.48%
Benchmark before using
INT8 search + rescore
384
int8
Yes
0.545
-0.04%
Best quantized option
Binary search
384
binary
No
0.475
-12.93%
Not recommended by default
Binary search + rescore
384
binary
Yes
0.543
-0.44%
Strong compression when rescoring is available
FAQ
Do I need a prefix like query: or passage: ? — No. bekko is trained without prefixes, so you encode raw text for both queries and documents. If you come from the multilingual-e5 family, just drop the prefixes.
Which languages are covered? — 100+ languages, inherited from the mmBERT base model. Coverage is broad but uneven, so evaluate on your own language and domain before deployment (see Limitations).
Which file should I load for my runtime? — PyTorch: the default safetensors weights. Fastest CPU inference: openvino/openvino_model.xml. Browser / ONNX Runtime: onnx/model.onnx. Files named _not_default / _not_recommended are comparison artifacts, not deployment choices.
Can I make the embeddings smaller? — Yes — pass truncate_dim=256 (or 128 / 64). See Truncation and Quantization for the quality cost.
Can it really run in a browser? — Yes. Try the bekko-embedding-web demo — the model runs fully client-side with Transformers.js.
Limitations
Evaluation scope and deployment considerations
Bekko is optimized primarily for multilingual retrieval. Its strongest MMTEB results are Retrieval, Reranking, BitextMining, and STS. It is not intended to be state of the art across every embedding task category.
Bekko is a bi-encoder embedding model, not a cross-encoder reranker. MMTEB Reranking scores measure bi-encoder similarity scoring. Use a dedicated cross-encoder when maximum reranking accuracy is more important than throughput.
Support for 100+ languages reflects training-data coverage. Quality varies by language and domain, so evaluate on your target data before deployment.
HAKARI-Bench is maintained by the model author and should be read alongside the independently maintained MMTEB suite. Bekko's MMTEB results use the same 131-task set and aggregation rules as the referenced snapshot, but await submission through the official leaderboard pipeline.
Throughput varies with text lengths, batch size, backend, software versions, and hardware. Use the benchmark figures as comparative measurements, not guaranteed production latency.
Transformer-weight qint8 artifacts are experimental and can lose retrieval quality or behave differently across CPU architectures. The default ONNX/OpenVINO artifacts only compress the static token embedding table and are the recommended deployment files.
The name "bekko"
bekko (/ˈbek.koː/) is a coined name that joins two pieces of Japanese tradition:
akabeko (赤べこ) — the red ox that has been cherished in Japan for centuries as a guardian charm, believed to ward off illness and misfortune.
bekko-iro (鼈甲色) — a beautiful traditional Japanese color: a warm, translucent, amber-like hue.
The name pairs the protective spirit of the red ox with the quiet beauty of this classic amber tone.
Paper
For full technical details, see Bekko Embedding: Parameter-Efficient Multilingual Retrieval with Ultra-Compact Encoders.
Citation
If you use bekko-embedding in your work, please cite: