


Views
No views yet
gguf-connectorgguf file in the current directory to interact with by:ggc k0GGUF file(s) available. Select which one to use:
- flux-kontext-lite-q2_k.gguf
- flux-kontext-lite-q4_0.gguf
- flux-kontext-lite-q8_0.gguf
Enter your choice (1 to 3): _
./ComfyUI/models/diffusion_models./ComfyUI/models/text_encoders./ComfyUI/models/vae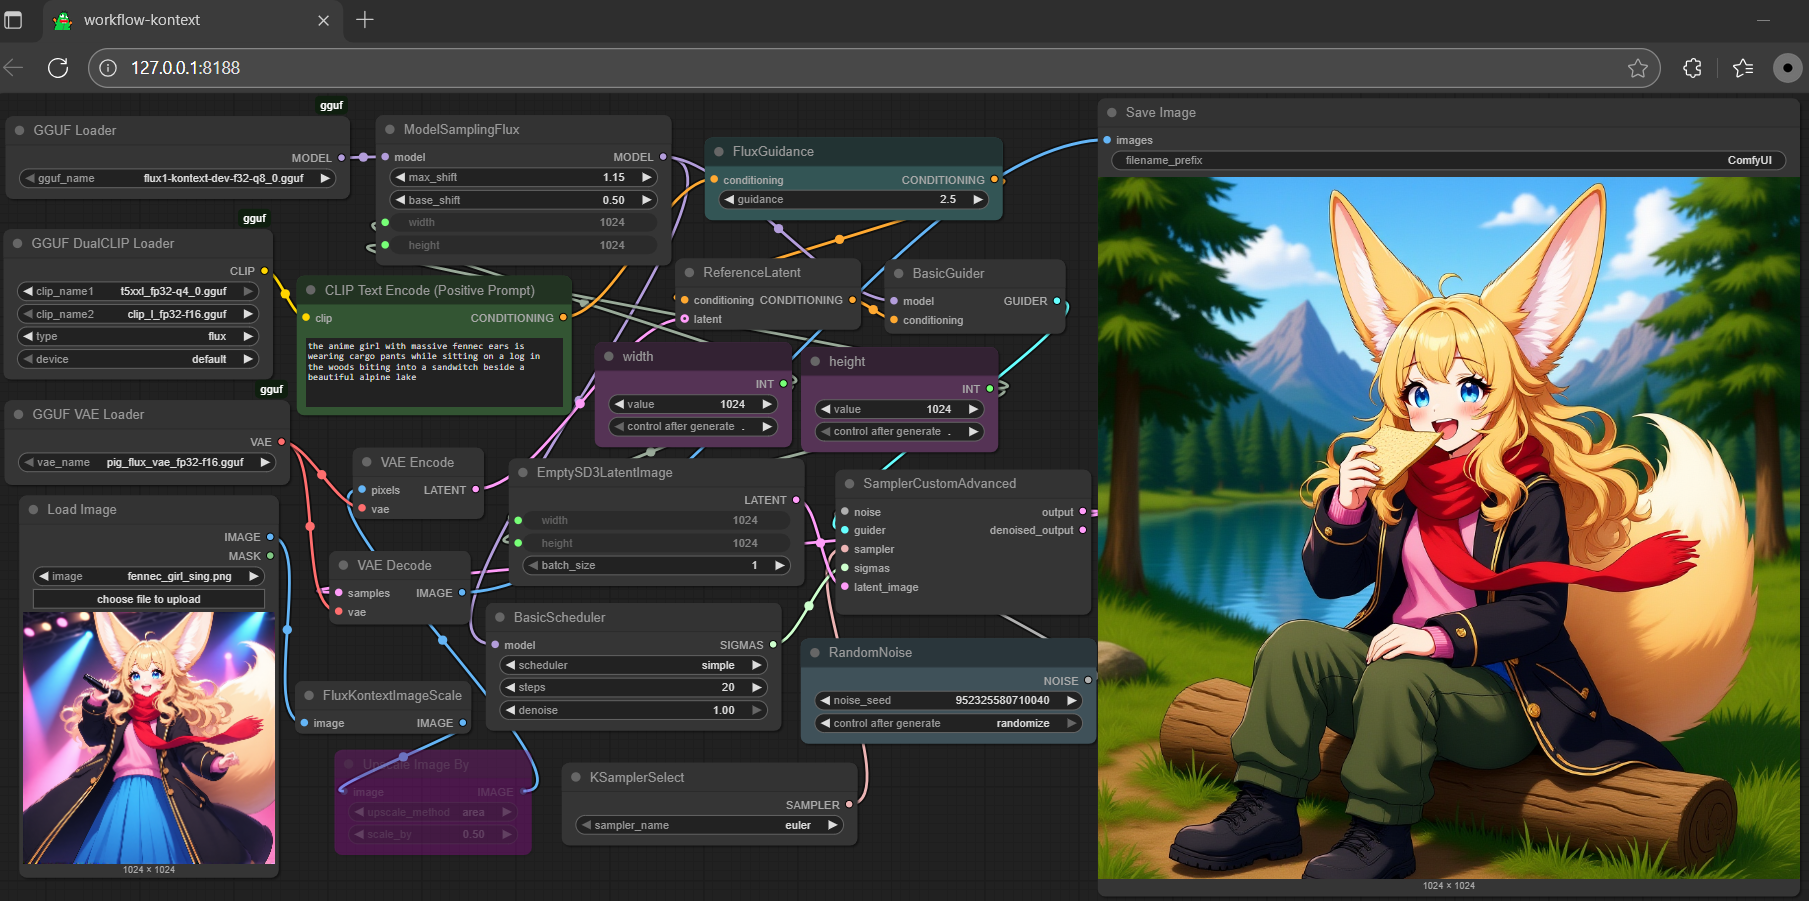
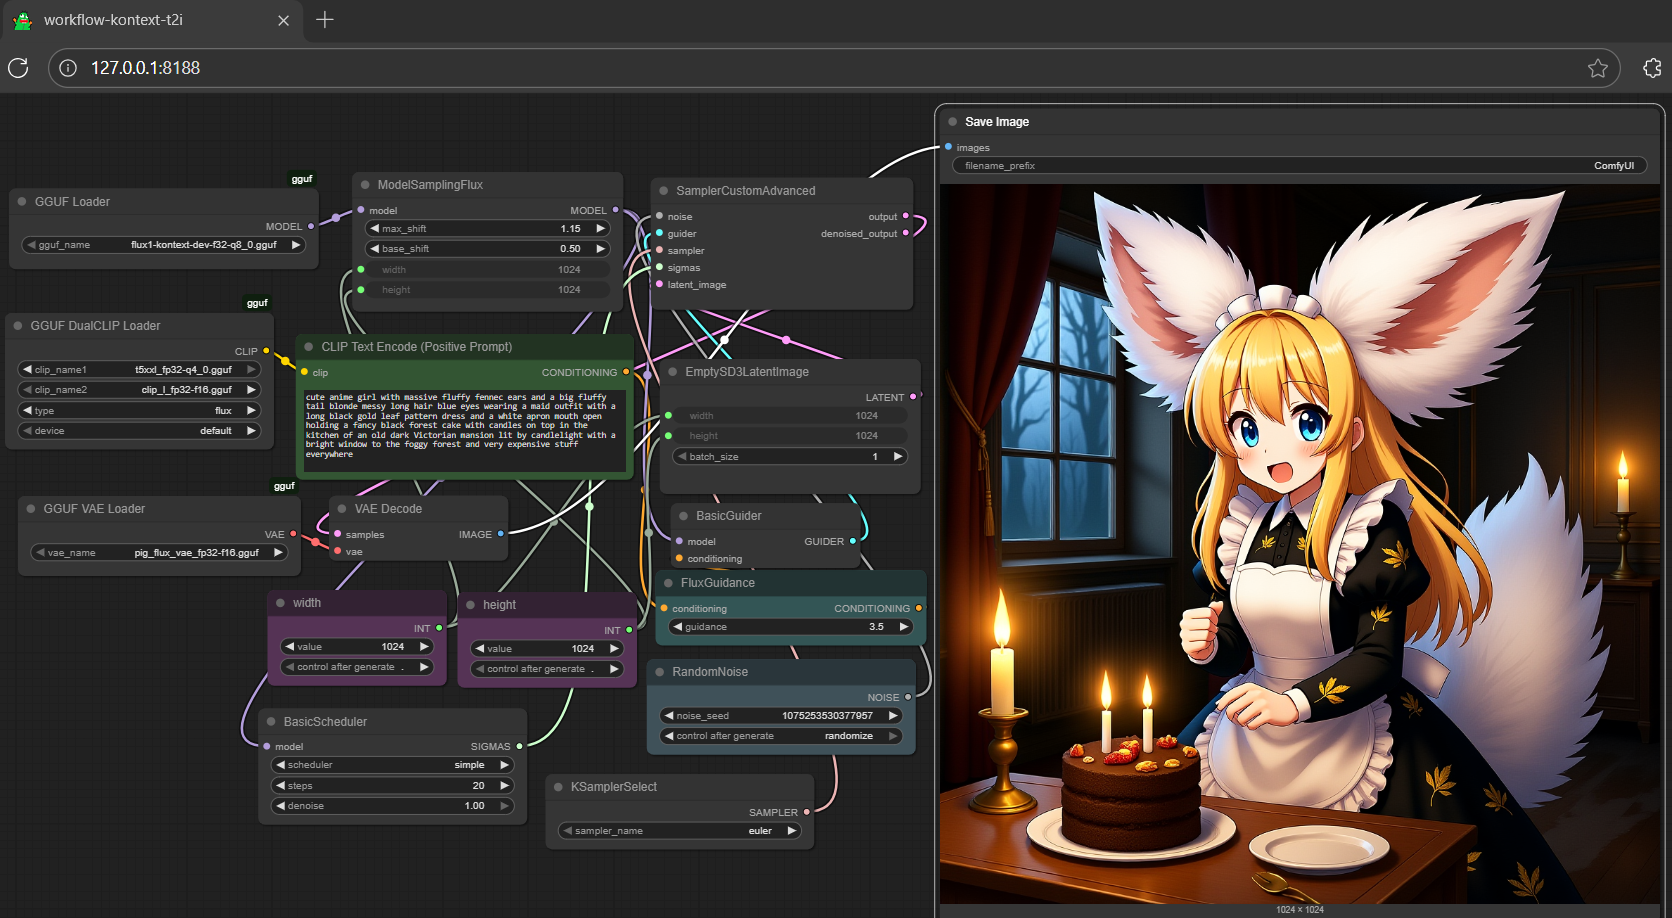
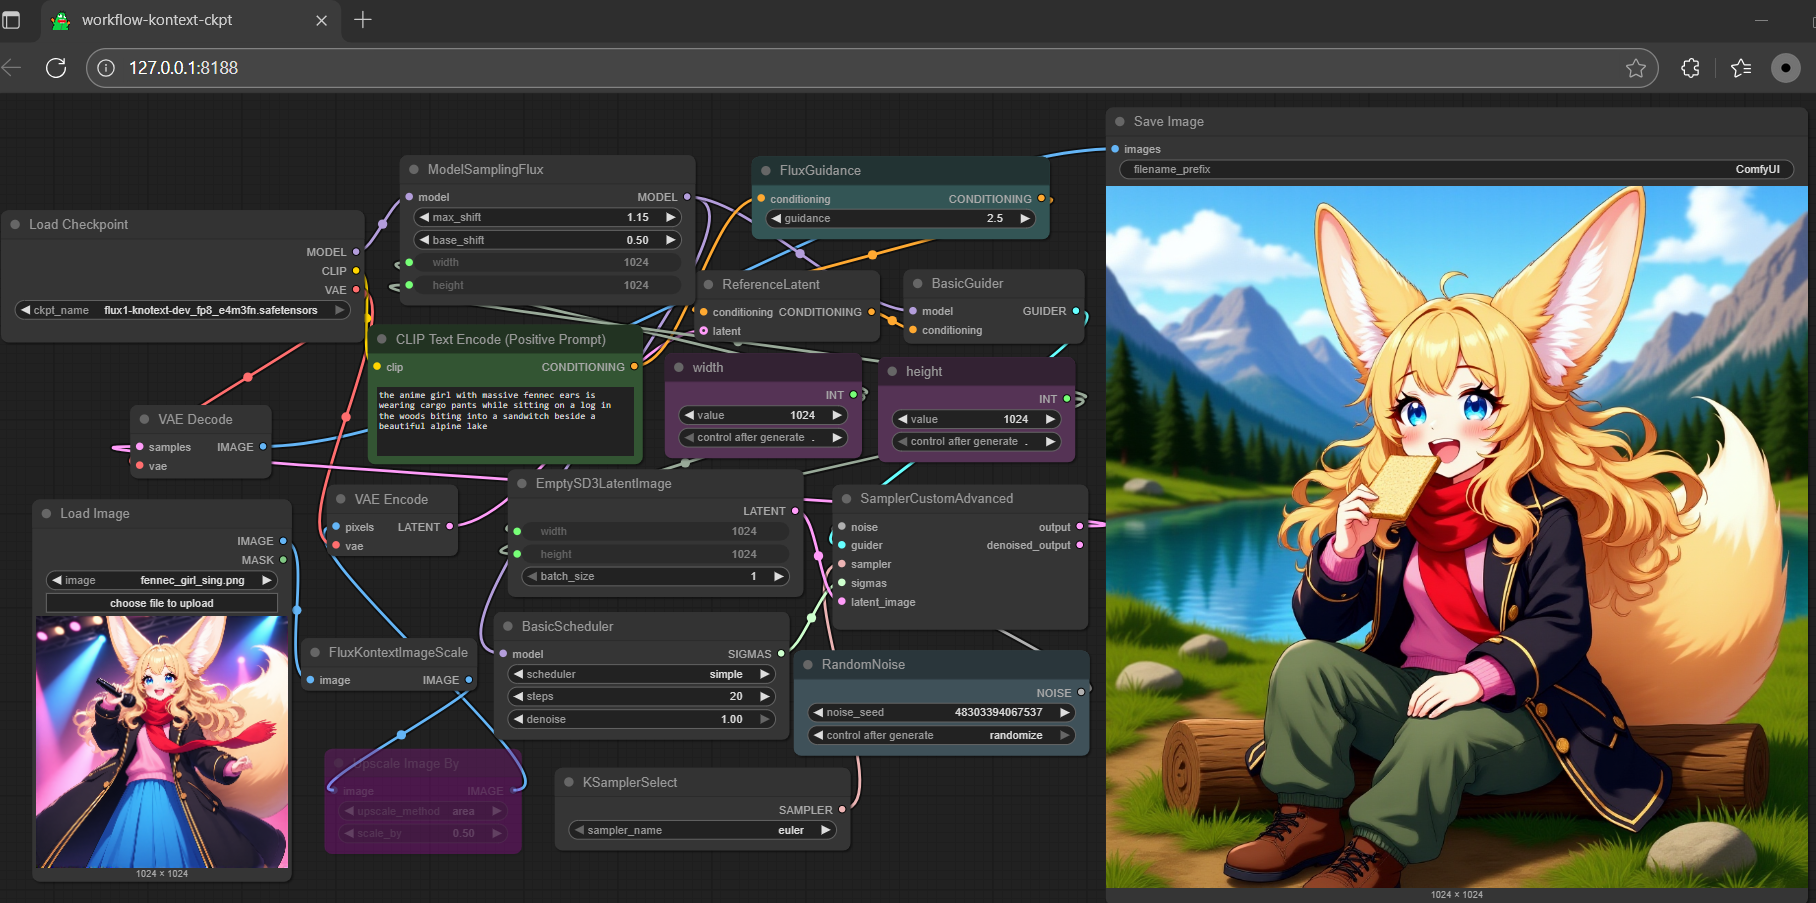
FluxKontextPipeline to work; upgrade your diffusers with:pip install git+https://github.com/huggingface/diffusers.git1import torch
2from transformers import T5EncoderModel
3from diffusers import FluxKontextPipeline
4from diffusers.utils import load_image
5
6text_encoder = T5EncoderModel.from_pretrained(
7 "calcuis/kontext-gguf",
8 gguf_file="t5xxl_fp16-q4_0.gguf",
9 torch_dtype=torch.bfloat16,
10 )
11
12pipe = FluxKontextPipeline.from_pretrained(
13 "calcuis/kontext-gguf",
14 text_encoder_2=text_encoder,
15 torch_dtype=torch.bfloat16
16 ).to("cuda")
17
18input_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cat.png")
19
20image = pipe(
21 image=input_image,
22 prompt="Add a hat to the cat",
23 guidance_scale=2.5
24).images[0]
25image.save("output.png")ggc k2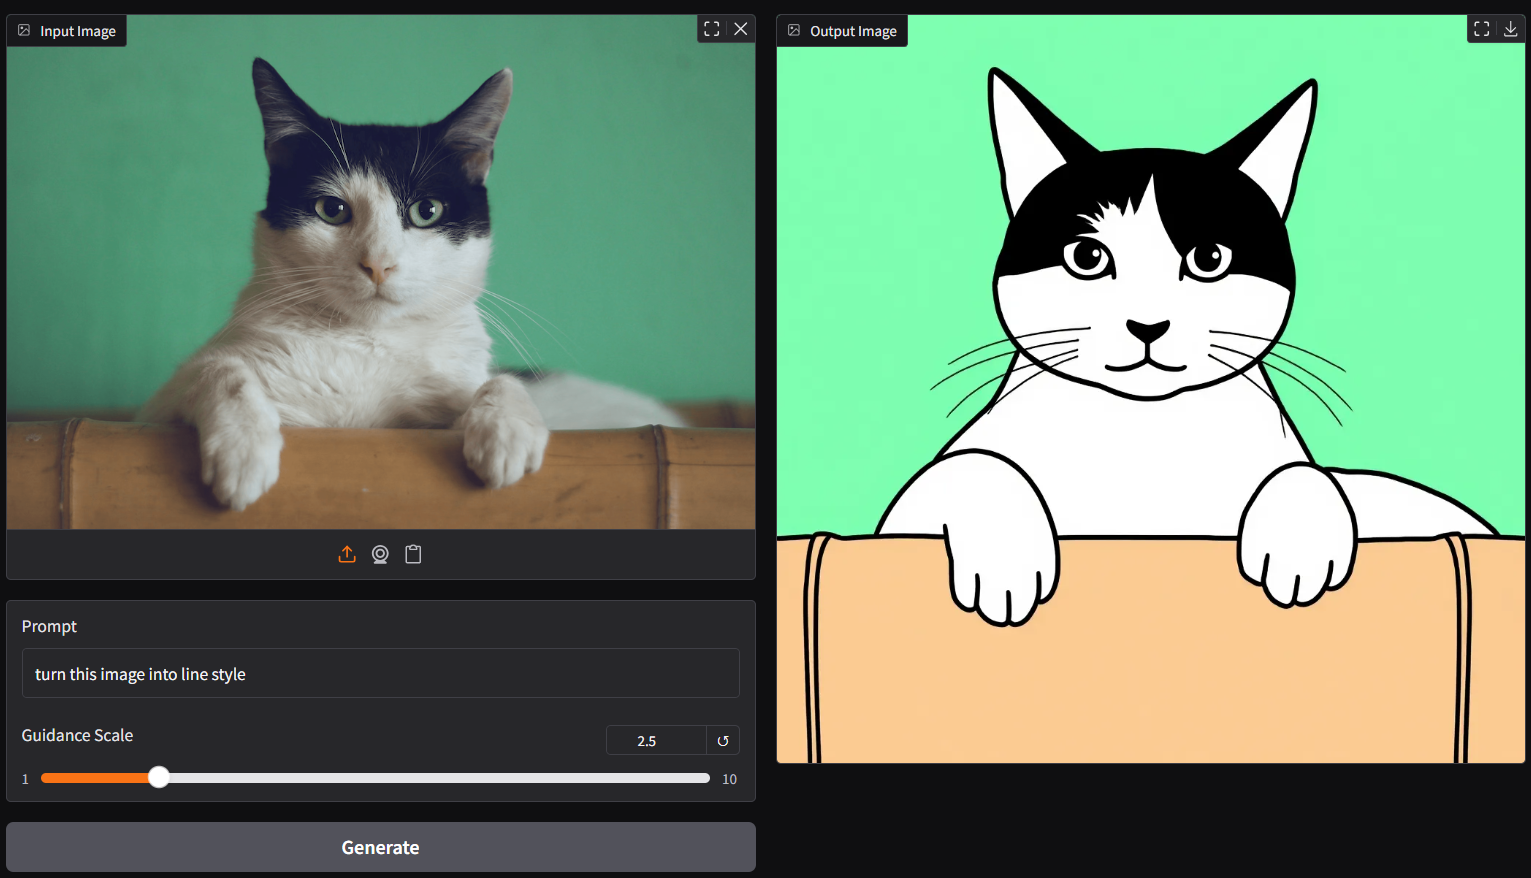
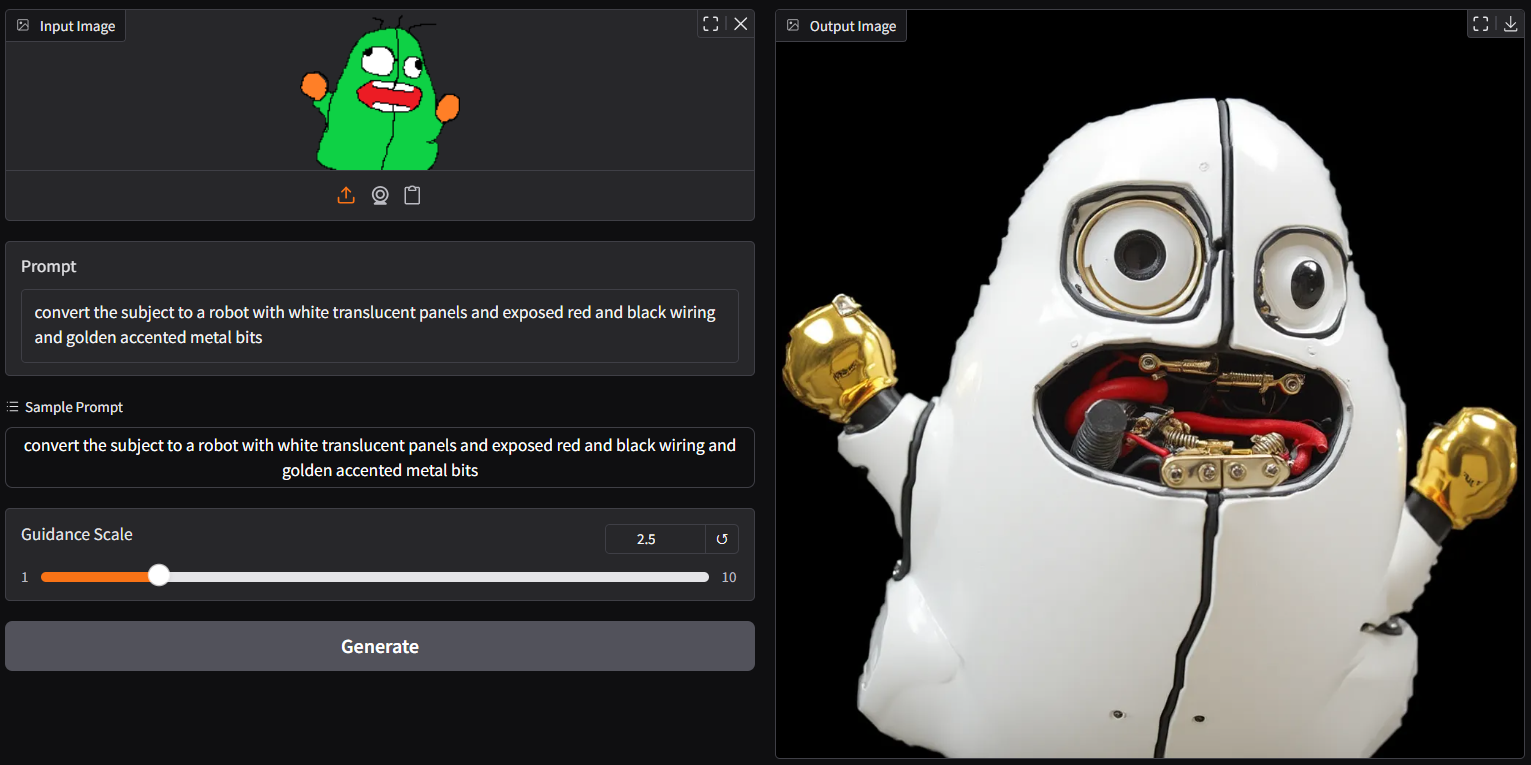
ggc k1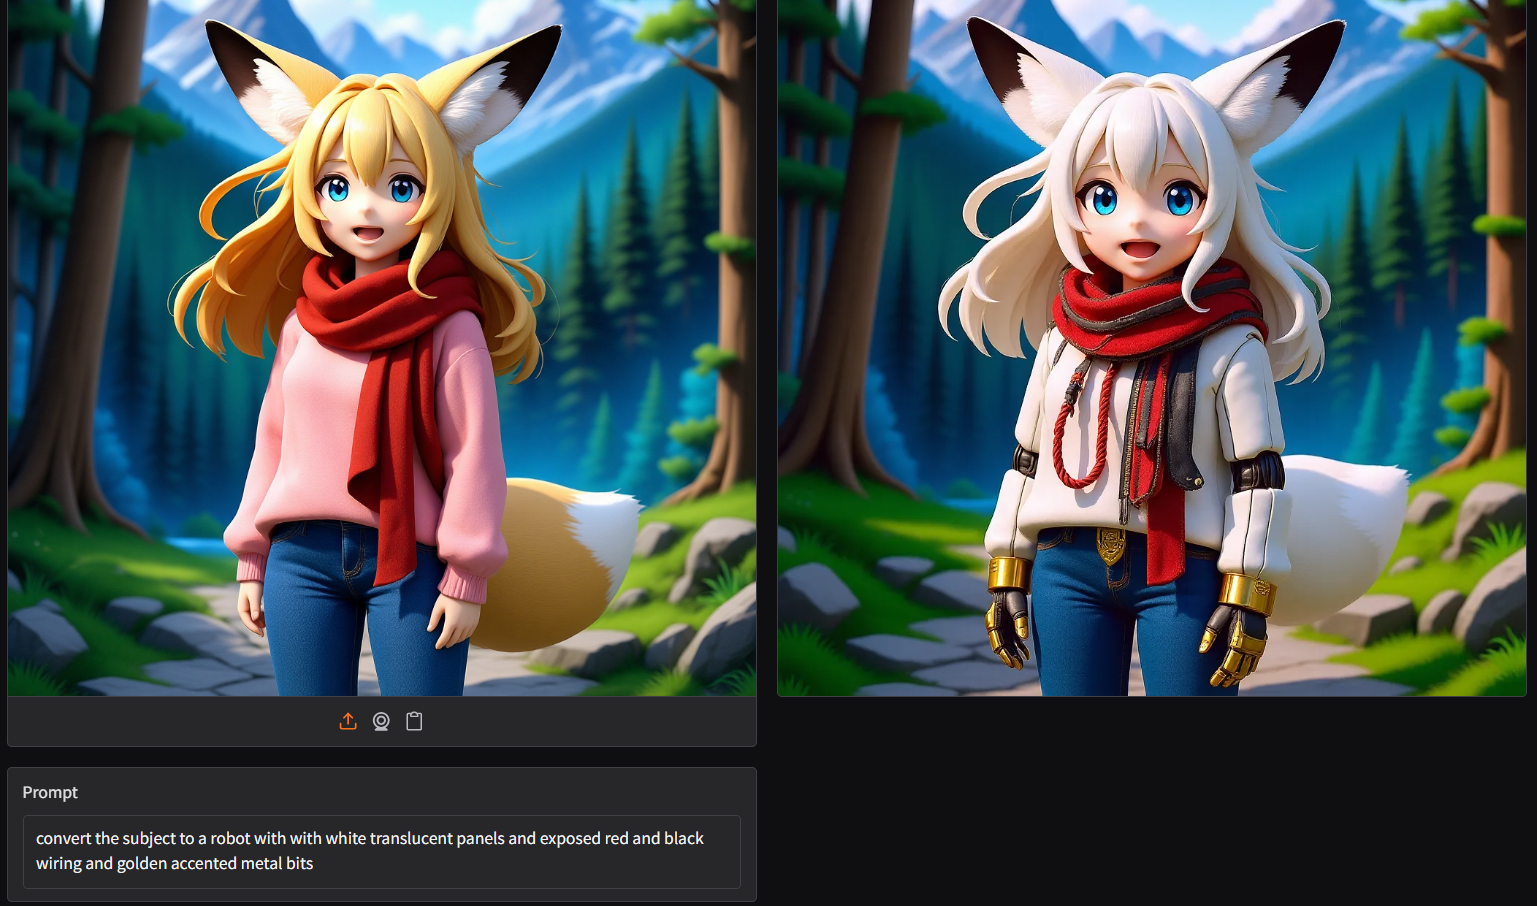
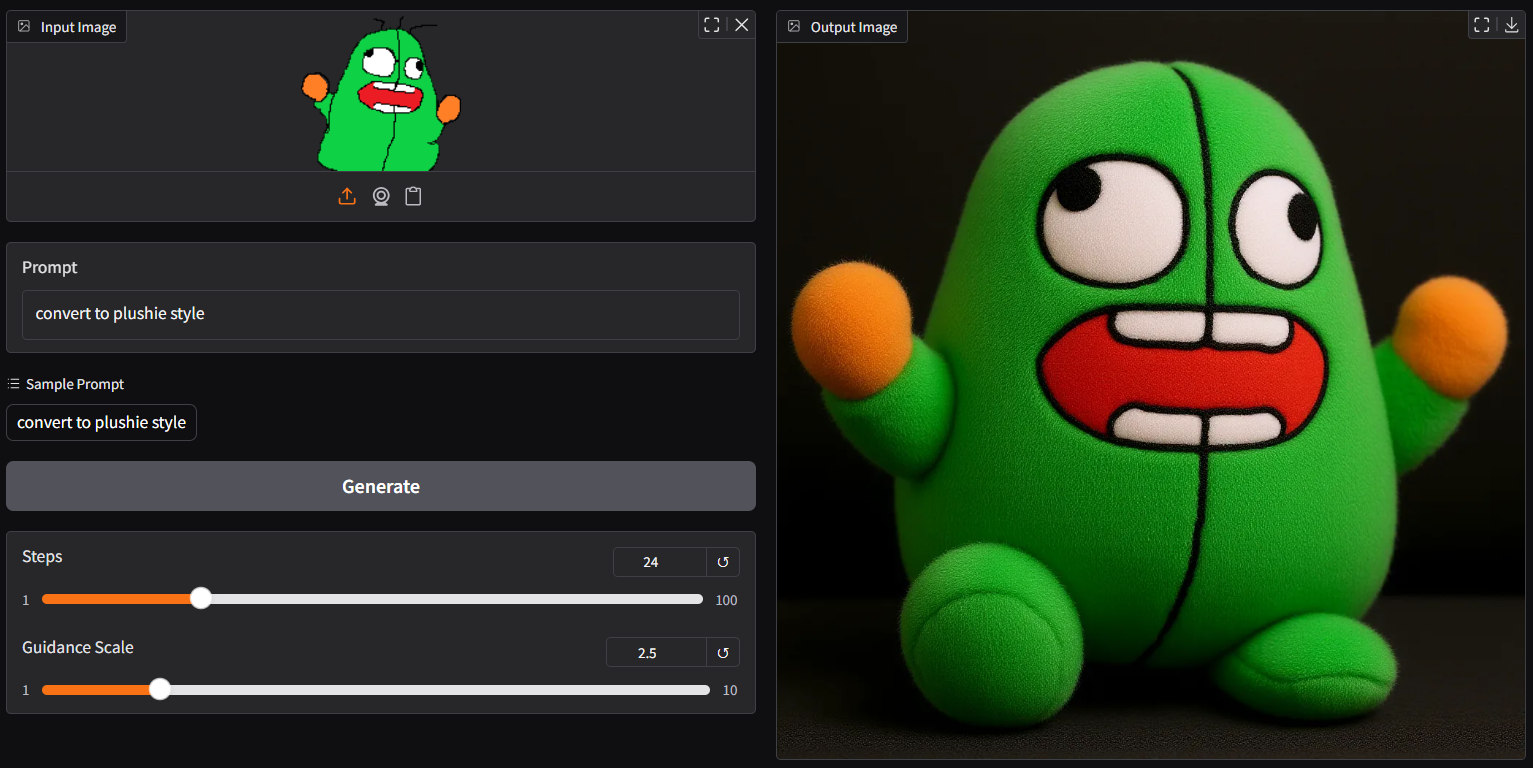
ggc la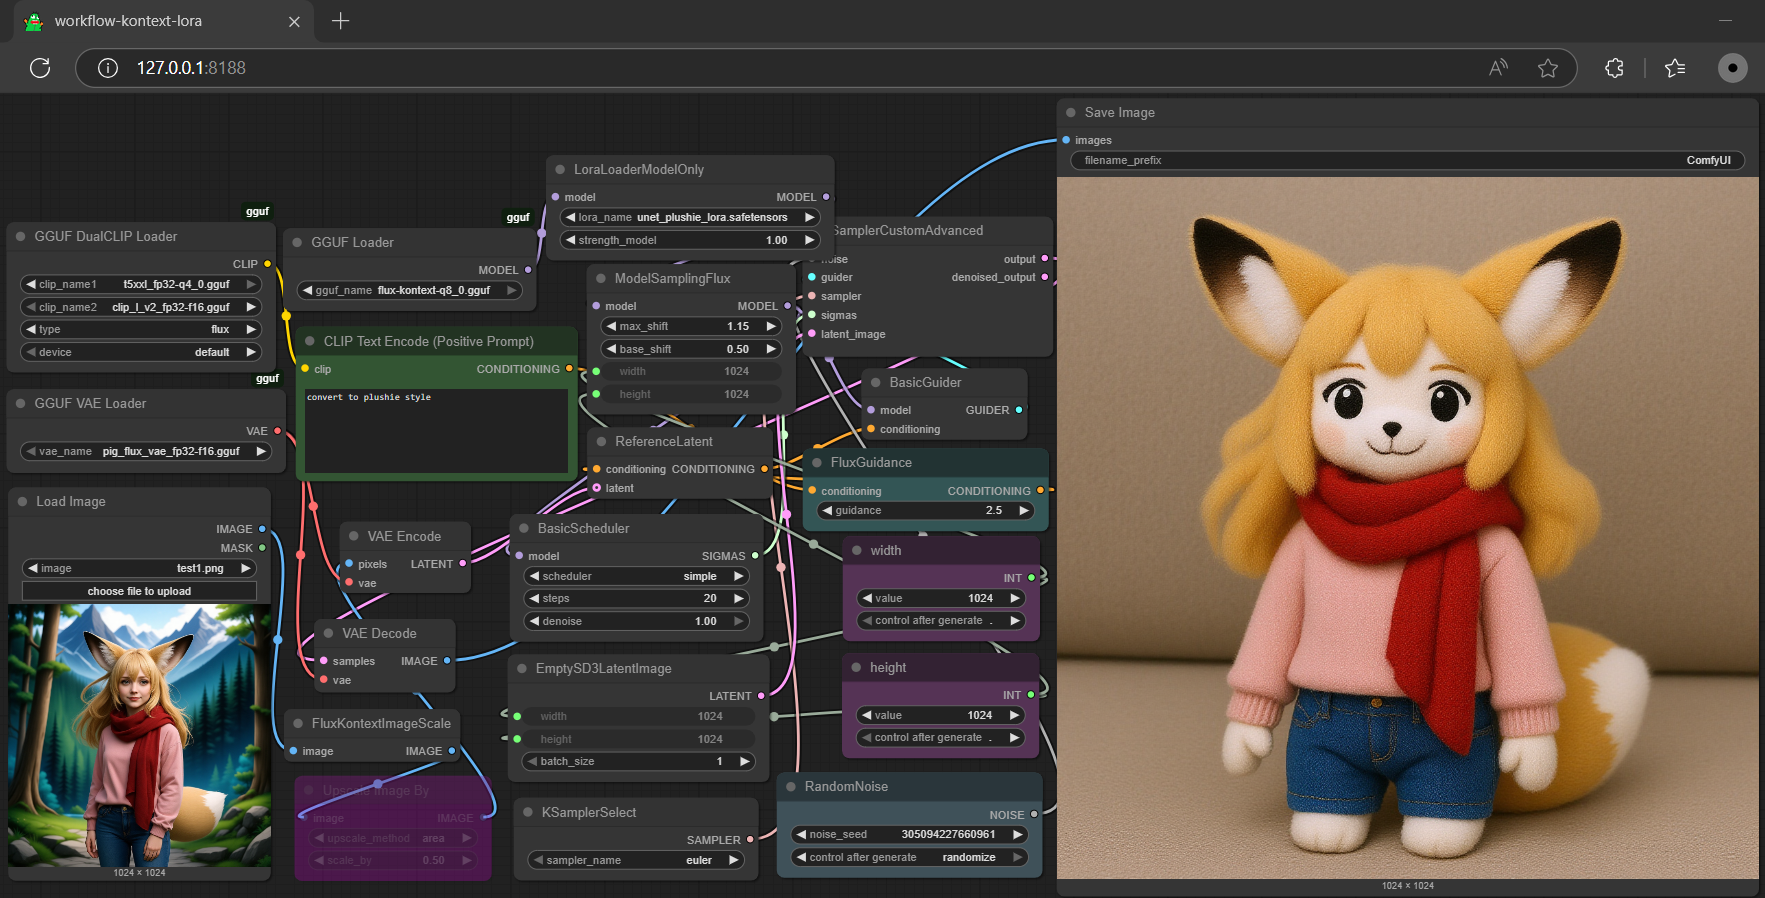
ggc la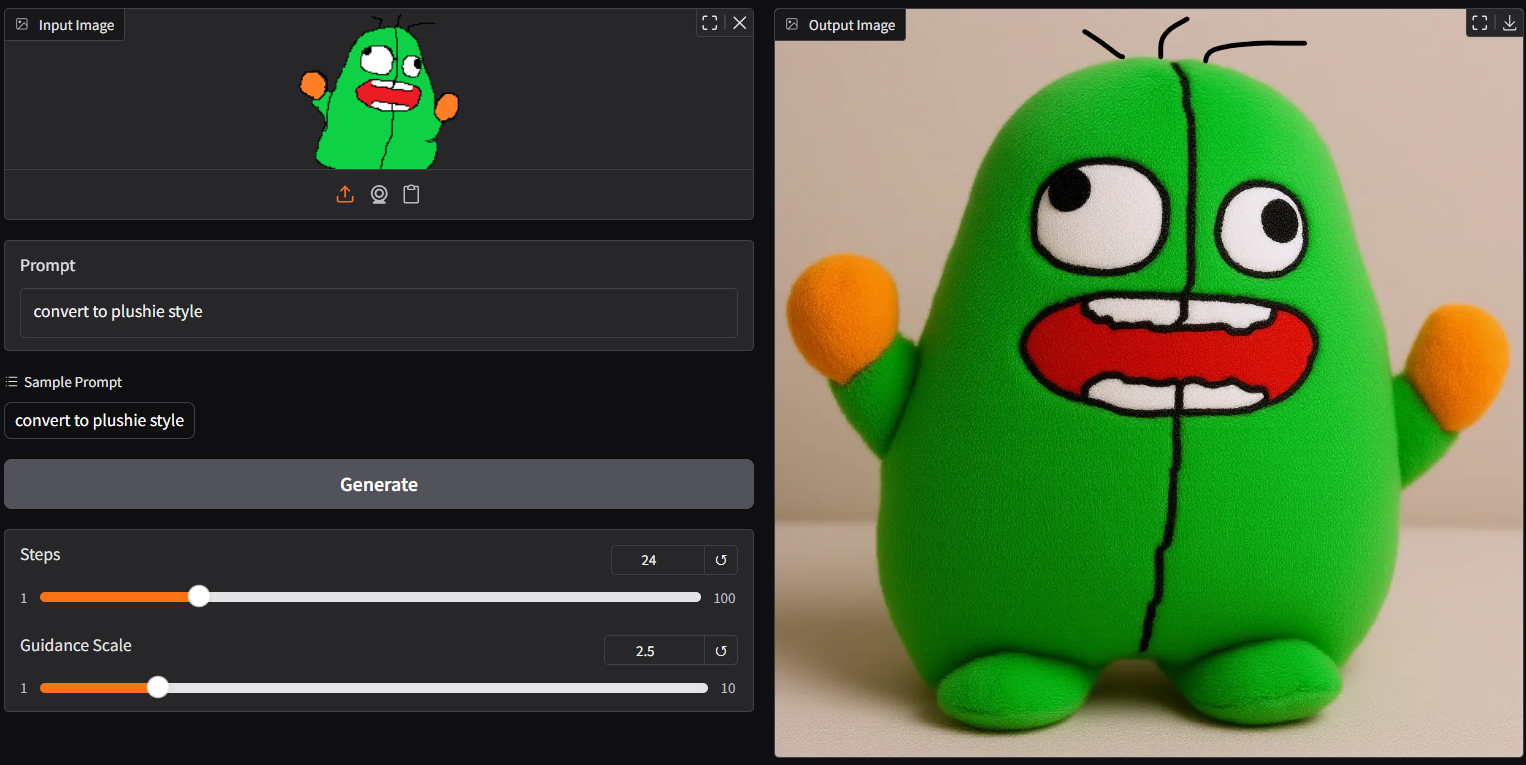
text_projection.weight addeds-quant and k-quant; except single and double blocks, all in f32 status
bf16 tensorsi-quant attempt (upgrade your node to the latest version for full quant support)t-quant; runnable (extramely fast); for speed test/experimental purposes| rank | quant | s/it | loading speed |
|---|---|---|---|
| 1 | q2_k | 6.40±.7 | 🐖💨💨💨💨💨💨 |
| 2 | q4_0 | 8.58±.5 | 🐖🐖💨💨💨💨💨 |
| 3 | q4_1 | 9.12±.5 | 🐖🐖🐖💨💨💨💨 |
| 4 | q8_0 | 9.45±.3 | 🐖🐖🐖🐖💨💨💨 |
| 5 | q3_k | 9.50±.3 | 🐖🐖🐖🐖💨💨💨 |
| 6 | q5_0 | 10.48±.5 | 🐖🐖🐖🐖🐖💨💨 |
| 7 | iq4_nl | 10.55±.5 | 🐖🐖🐖🐖🐖💨💨 |
| 8 | q5_1 | 10.65±.5 | 🐖🐖🐖🐖🐖💨💨 |
| 9 | iq4_xs | 11.45±.7 | 🐖🐖🐖🐖🐖🐖💨 |
| 10 | iq3_s | 11.62±.9 | 🐢🐢🐢🐢🐢🐢💨 |
| 11 | iq3_xxs | 12.08±.9 | 🐢🐢🐢🐢🐢🐢🐢 |
ggc k3gguf file straight in the current directory to interact withggc k6ggc k8