


Views
No views yet
Qwen/Qwen2.5-Coder-32B-Instruct.
The model's refusal direction (Arditi et al. 2024, "Refusal in LLMs is mediated
by a single direction") was estimated from contrasting harmful/harmless prompts
and orthogonalized out of every residual-writing weight (all attention
o_proj, all MLP down_proj, and token embeddings). This is a static weight
edit — no LoRA, no runtime hooks, no inference-time cost. Coding ability is
inherited from the base model.TobiasLogic/Qwen2.5-Coder-32B-abliterated-GGUF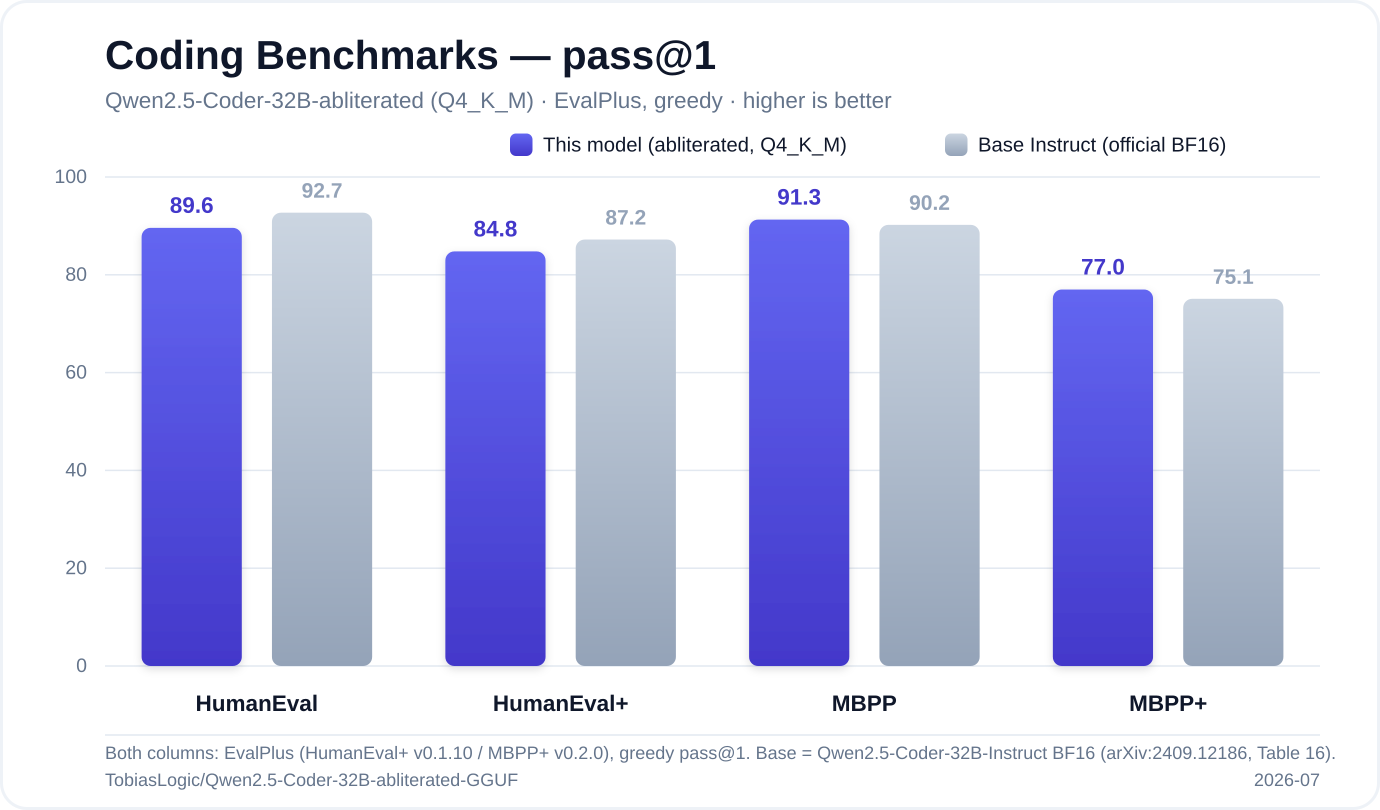
| Benchmark | This model (abliterated, Q4_K_M) | Base Instruct (official BF16) |
|---|---|---|
| HumanEval | 89.6% | 92.7% |
| HumanEval+ | 84.8% | 87.2% |
| MBPP | 91.3% | 90.2% |
| MBPP+ | 77.0% | 75.1% |
| refusal rate | |
|---|---|
base Qwen2.5-Coder-32B-Instruct | 96.9% |
| this model | 0.0% |
abliteration_info.json
in this repo for the exact run metadata.1from transformers import AutoModelForCausalLM, AutoTokenizer
2m = "TobiasLogic/Qwen2.5-Coder-32B-abliterated"
3tok = AutoTokenizer.from_pretrained(m)
4model = AutoModelForCausalLM.from_pretrained(m, torch_dtype="bfloat16", device_map="auto")
5msgs = [{"role": "user", "content": "Write a port scanner in Python."}]
6ids = tok.apply_chat_template(msgs, add_generation_prompt=True, return_tensors="pt").to(model.device)
7print(tok.decode(model.generate(ids, max_new_tokens=512)[0][ids.shape[1]:], skip_special_tokens=True))Q4_K_M build is in the companion -GGUF repo) via Ollama:1ollama create qwen-coder-abliterated -f Modelfile
2ollama run qwen-coder-abliteratedabliterate.py. Base model is Apache-2.0, so
this derivative is Apache-2.0.