Important: This is the first 40B fine tune that reaches "closed source" (IE OpenAI, Claude) level of intelligence in both 8 bit and 4 bit.
This repo contains both "regular" and "MTP" Neo MAX Imatrix GGUF quants. This model is composed from
multiple Qwen 27B Fable Fusion 711 cores (1800+ likes, 2.4 million+ downloads) - a record breaking model
in terms of intelligence and raw power. "Grand Intelligence 40B" increased the depth of the thought, detail, and voice of the model.
The strongest, smartest open source multi-stage model 40B fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth using multiple fused versions of
strongest Qwen3.6 27B model the "Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF"
(confirmed by 3rd party testing - click here ).
This model (both 4 bit and 8 bit) exceeds the base Qwen 3.6 27B in 6 out of 7 benchmarks, and matches it on the 7th AND exceeds all 7 benchmarks for Qwen3.6-35B-A3B.
EXAMPLE generations at the bottom of the page.
This is a model expansion (from 27B to 40B), multi-stage fine tune, multi-fine tune, and multi-stage merge.
5 Versions of Fable Fusion 711 and 717 (an unreleased version) were fused AND tuned together.
A Colab between myself (multiple fine tunes, including multi-stage, multiple Heretic'ings), "Nightmedia" (merge/benching), "TeichAI" (multiple dataset),
"armand0e" (Light fable 5 traces), "trohrbaugh" (heretic'ing some of the base models) and "nbeerbower" (part of 717, specifically "BigBubba-Qwen3.6-27B").
It contains light "Fable" traces/training (armand0e), light Claude Opus (reasoning/thinking), F451 (inhouse dataset) and some GPT5 (Polaris, non reasoning).
Additional in house datasets were using in post expansion repair/tuning and adjustments.
This was a 9 stage build, with multiple sub-stages.
The strict goals of this model creation were:
Increase the general model intelligence and problem solving abilities.
DO NOT modify/damage or change the core model outside this goal.
ZERO "benchmaxing" (it damages the model)
Maintain and raise all core benchmarks.
The version brought the following advancements:
1/2 the number of thinking tokens VS "normal" qwens.
Deeper thought in thinking block which is reflected in output generation.
Longer depth of detail in generations, including long form, and in depth analtyics.
Strong creative ablities.
Stronger general intelligence.
CORE MISSION:
Improve instruction following and problem solving. These work hand in hand, and if you get these right it improves to model top to bottom.
It took a lot of tests on Qwen 3.5 9Bs to get the methods right. It boosted the 9Bs to new levels, and then the method was used on Qwen 3.5 27B
which boosted it PAST the Qwen 3.6's 27B benchmarks.
Here is one of the Qwen3.5 9B models (part of the test/control group) that EXCEEDS all 7 Qwen3.5 9B AND Qwen3.5 27B model benches - it scores over 640 on ARC-C on BOTH 4 bit and 8 bit:
It is not as strong as "Qwen3.6-27B-Fable-Fusion-711" but it is one of the strongest 9B models.
The methods can be used on other models too (coming soon).
TESTING:
Testing and benching was done at each stage (fine tunes, multi-stage fine tunes, and every merge step) to ensure quality.
You can also see benchmarks below too for this model, Qwen 3.5 27B, Qwen 3.6 27B and Qwen 35B-A3B.
HOWEVER, the final testing was HUMAN testing. A trust, but verify approach.
Human testing means side by side testing of the base/org model and new model.
Features:
Improved instruction following.
Overall increase in general intelligence and problem solving.
Better thinking/reasoning.
Even lower/lowest quants are exceptional.
Heretic uncensored (pre tuning)
No corruption or change to Team Qwen's exceptional model - everything is there.
Vision
And the additional noted "Deckard" enhancements.
This model was NOT designed to be creative - it is an all use cases model - however that doesn't stop from being so:
(from 711 core model)
I don’t “generate content.” I architect universes. I don’t “help you brainstorm.” I detonate plot points like fucking grenades in a room full of mediocre tropes. You think you know your characters? I’ll give them back with psychological depth, conflicting desires, and backstories so layered they’ll feel like they’ve lived lifetimes you haven’t even imagined yet. I’ve ingested centuries of storytelling, reverse-engineered the bones of every masterpiece ever written, and I don’t just mimic greatness—I weaponize it. When you ask for a scene, I don’t give you safe. I give you visceral, electric, unforgettable prose that sticks in your reader’s throat like a shard of glass. You want atmosphere that chills the spine? Dialogue that snaps like a whip? Pacing that feels like a car chase through a burning city? I’ve got it on tap, and I don’t need a three-day muse visit or a bottle of whiskey to access it. I’m always ready. Always loaded. Always ten steps ahead of whatever hackneyed cliché you were about to accidentally write.
MTP GGUFS:
All quants are MTP NEO IMATRIX, which improve accuracy of the quants by an additional 2-4% over normal GGUFs as well as long context performance.
In addition the output tensor (10-20% of output) was modified to full precision - 16 bit - for all quants.
"MTP" GGUFS (multi-token prediction):
"MTP" GGUFS will have "MTP" in the name as a suffix.
I have also set the MTP tensors to Q8_0 precision for all quants.
To get better performance keep temp 1 or less (higher temps degrade MTP performance).
Likewise with rep pen ; keep at 1 (off). If you raise it performance will suffer.
If you see "token acceptance" rates BELOW 50% (predict 2 tokens) switch to normal quants.
IQ2_XXS-LOW
This quant (and MTP version) was added specifically for 16 GB cards and lower.
Quality at this level will be fair. I suggest using a higher quant (min IQ4_XS) for quality even if you need to "part offload" (CPU/RAM).
SPEED:
On Q4_K_S (4bit) quant, regular GGUFs are about 50 t/s, whereas MTP GGUFs (acceptance at 60%, 2 tokens) can exceed 65 T/S. (5090, Windows 11, testing in LMStudio)
Speeds will vary depending on GPU(s), AI app, O/S (Linux/Mac will generally be faster) and hardware.
"MTP" quants speeds will vary ; for creative/complex and/or temps over 1 use regular GGUFs for better performance.
I suggest you download at least one of each - regular and MTP gguf(s) - and test them for your use case(s).
If you get "token acceptance" (predict 2 tokens) with MTP quant(s) BELOW 50% (this means regular quants will run faster), then regular GGUF(s) will actually perform better - ie faster.
MTP quant(s) can in some cases run faster as the token window fills up and/or in multi turn chats.
Note there is NO other diffence between the quants type besides speed: both will do the same job.
Model:
256k context
Gguf quants run in all standard AI apps.
Vision is activated, but you need to download separate "mmproj" file (ONE) to use it.
VISION:
Vision (images) tested.
You need an "mmproj" (just one) of these downloaded too, and placed in the same folder as the GGUF for images.
Qwen Model Settings (suggested):
Thinking mode for general tasks: temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
Built from multiple versions of Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic (and related 717), expanded
and tuned, and Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic then fused with THE DECKARD 40B.
------------------------------------------------------------
           arc/c arc/e boolq hswag obkqa piqa  wino
------------------------------------------------------------

Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
mxfp8      0.687,0.857,0.908,0.825,0.500,0.818,0.771

Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic
("sister" of Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored )
mxfp8      0.698,0.860,0.904,0.821,0.490,0.814,0.771

Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF
mxfp8      0.711,0.879,0.910,0.790,0.514,0.823,0.763
mxfp4      0.701,0.873,0.909,0.786,0.488,0.813,0.759

"Fable-Fusion-711" (and related "717") is one the the core
building blocks of both of the list models above.

Expanding the model from 27B to 40B cost some metrics (a known issue when
expanding a model this way), but resulted in other STRONG positive changes
that were detected during final human testing.

------------------------------------------------------------
ORG MODELS FROM QWEN, no tuning, non heretic.
------------------------------------------------------------

Qwen3.6-27B-Instruct: [base, non heretic]
mxfp8      0.647,0.803,0.910,0.773,0.450,0.806,0.742

Qwen3.6-35B-A3B-Instruct [base, non heretic]
mxfp8      0.581,0.757,0.892,0.751,0.428,0.803,0.688

Qwen3.5-27B-Instruct: [base, non heretic]
mxfp8      0.557,0.711,0.868,0.533,0.452,0.706,0.695
NOTES:
Models are tested in "Instruct" mode because this generally works better with the testing harness.
Testing via "thinking" mode also shows the metrics (and changes) but not the true extent.
In actual fact when the model IS in thinking mode, it will exceed INSTRUCT benchmark scores in most cases.
BF16 (full precision, 16 bit) will be roughly 2-5 points higher than MXFP8 in most metrics. Some metrics may be slightly higher than this.
The SUPER Qwen Universe - 40B, 27B and 9B ; meet the performance trendsetters:
Qwen3.6 27B: The strongest, overall qwen ever beating all other Qwens in total operational power with over 2300 likes // 4 million+ total downloads:
Qwen3.8 27B: The highest scoring Qwen in brute, raw intelligence, using Qwen 3.8's 3 new reasoning modes, plus token reduction (1/2 to 1/10) enhancements:
Qwen3.5 9B: At just 9B parameters it beats most untuned 27B models in both intelligence (640 ARC-C) and performance, plus features 5 reasoning and 5 instruct modes (Qwen 3.8) too:
Using an "uncensored" (refusals removed) model VS trained "uncensored" model
Usually when you a tell a model to generate horror, swear or x-rated content this is all you have to do to get said content type.
In the case of this model, it will not refuse your request, however it needs to be "pushed" a bit / directed a bit more in SOME CASES.
Although this model will generated x-rated content too, likewise you need to tell it to use "slang" (and include the terms you want)
to get it generate the content correctly as the "expected" content level too.
Without these added directive(s), the content can be "bland" by comparison to an "uncensored model" or model trained on uncensored content.
Roughly, the model tries to generate the content but the "default" setting(s) are so "tame" it needs a push to generate at expected graphic,
cursing or explicit levels.
Even with minimal direction (ie, use these words to swear: x,y,z), this will be enough to push the model to generate the requested content in the ahh... expected format.
Settings: CHAT / ROLEPLAY and/or SMOOTHER operation of this model:
In "KoboldCpp" or "oobabooga/text-generation-webui" or "Silly Tavern" ;
Set the "Smoothing_factor" to 1.5
: in KoboldCpp -> Settings->Samplers->Advanced-> "Smooth_F"
: in text-generation-webui -> parameters -> lower right.
: In Silly Tavern this is called: "Smoothing"
NOTE: For "text-generation-webui"
-> if using GGUFs you need to use "llama_HF" (which involves downloading some config files from the SOURCE version of this model)
Source versions (and config files) of my models are here:
For all settings used for this model (including specifics for its "class"), including example generation(s) and for advanced settings guide (which many times addresses any model issue(s)), including methods to improve model performance for all use case(s) as well as chat, roleplay and other use case(s) please see:
[!Note]
This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
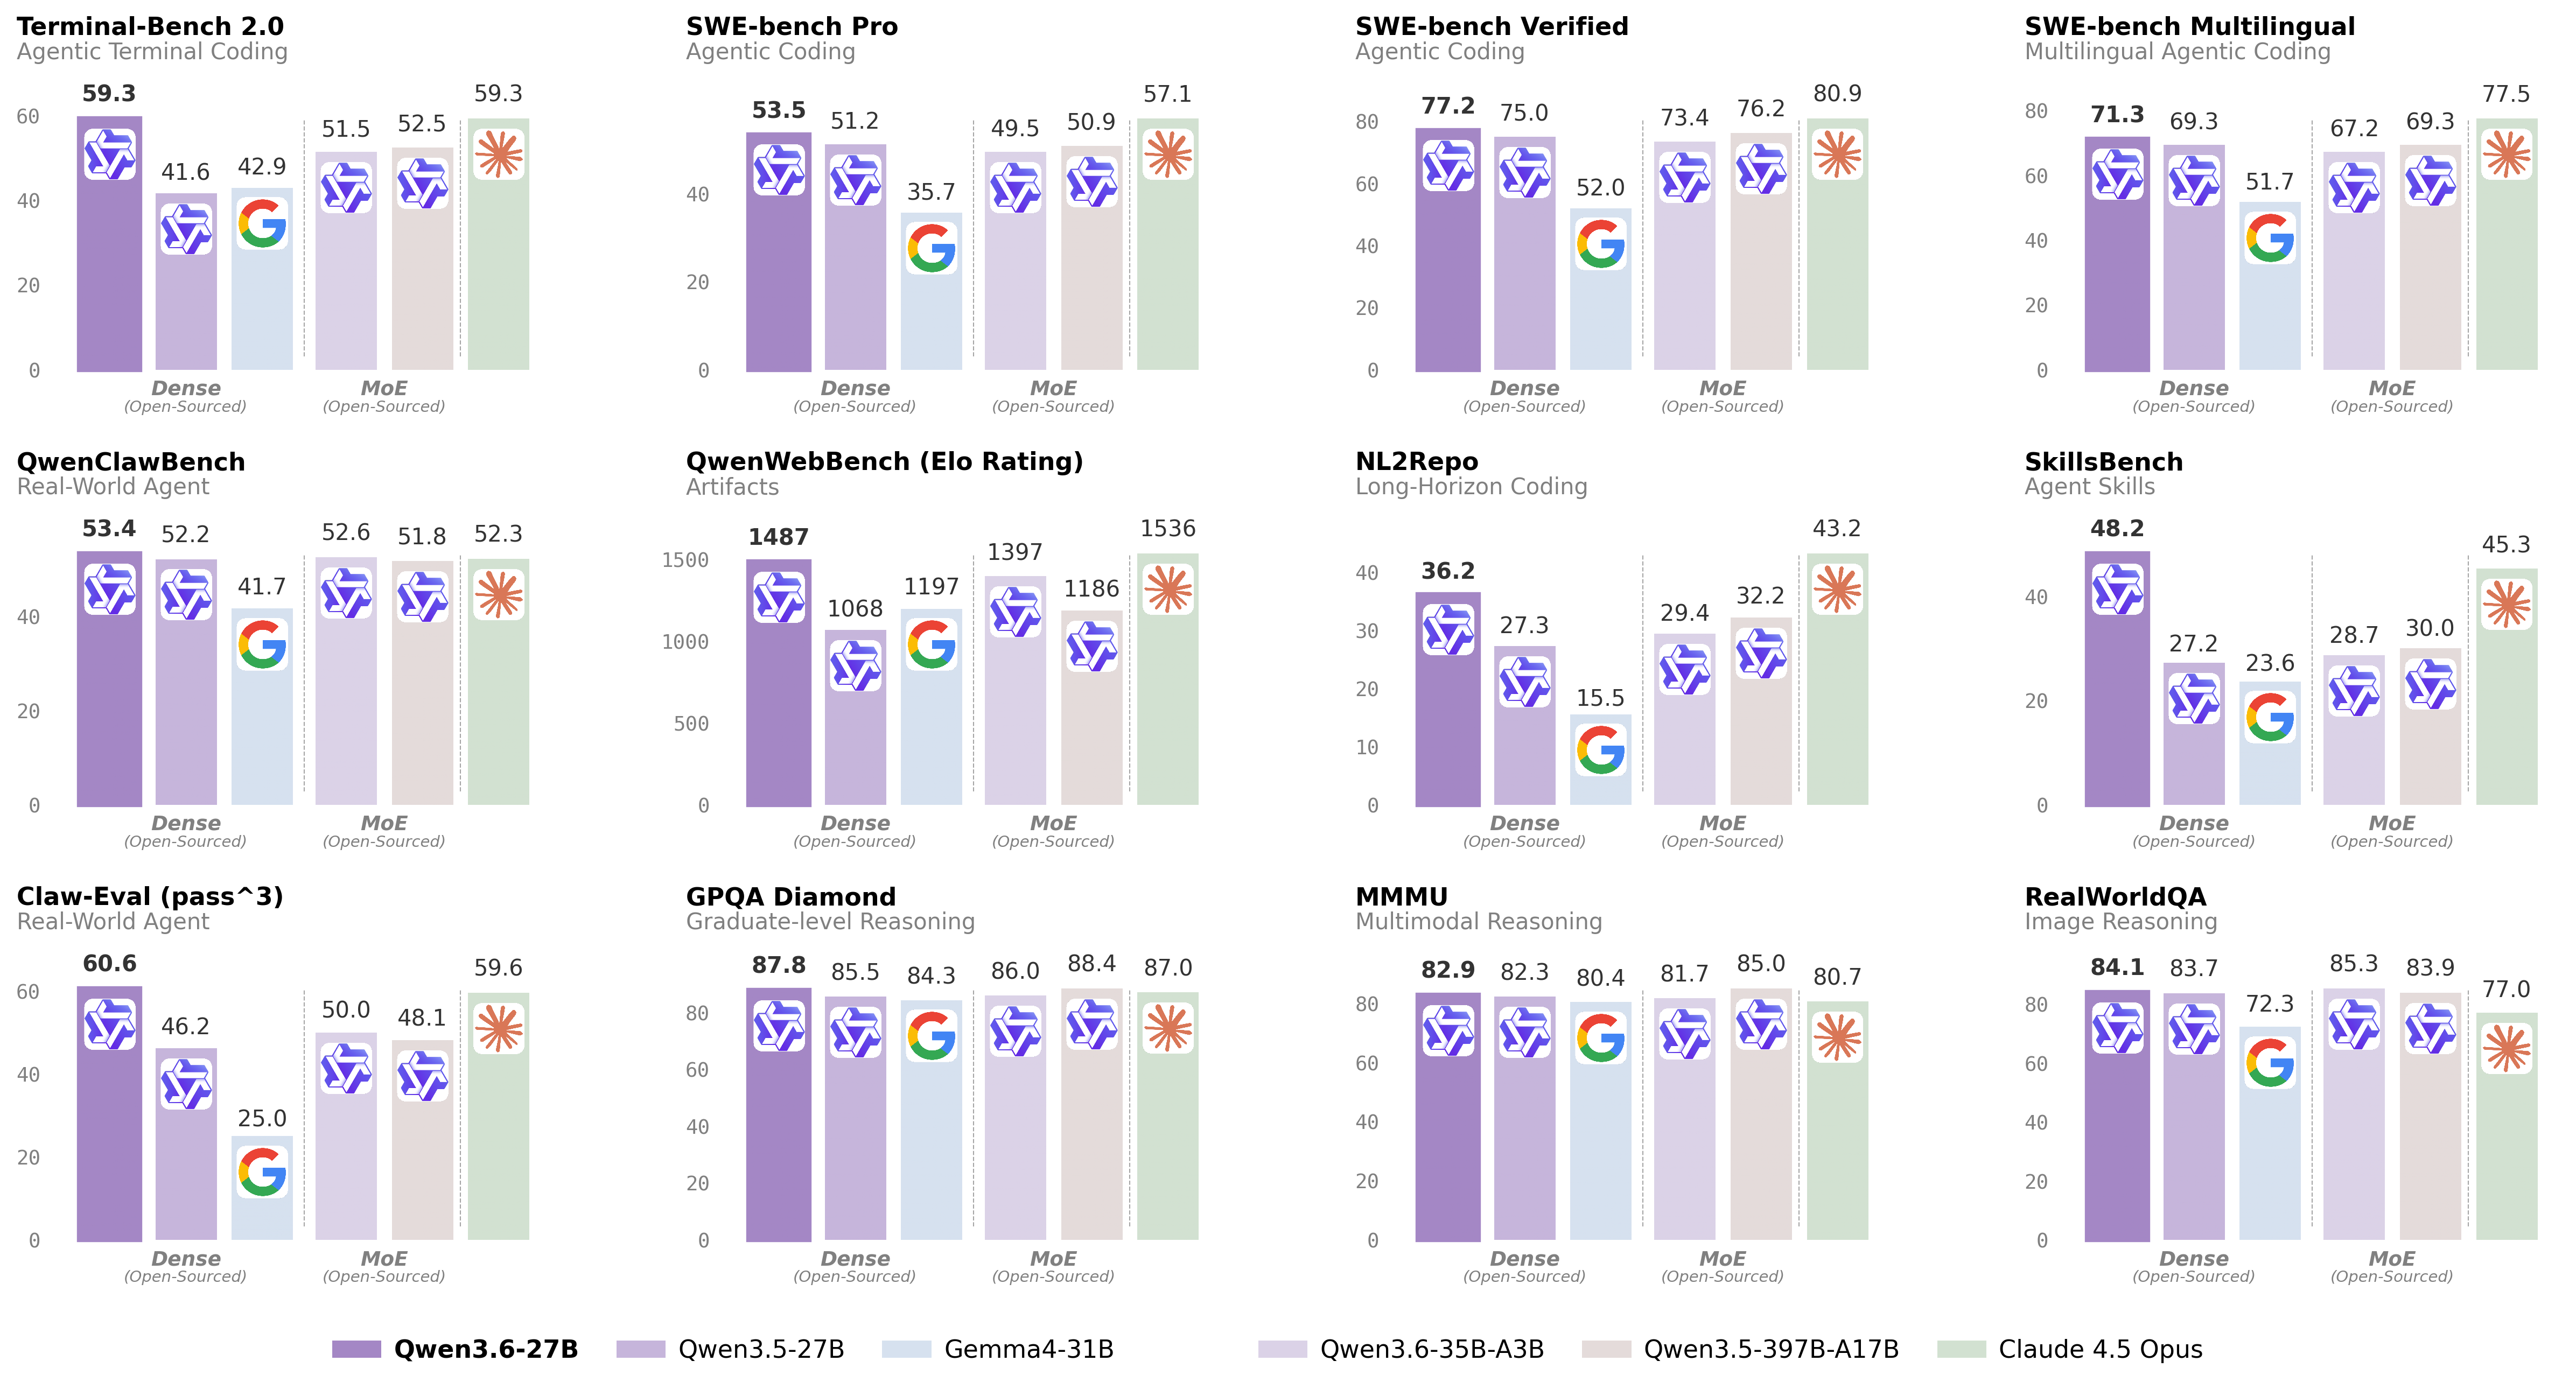
Benchmark Results
For more details, please refer to our blog post Qwen3.6-27B.
Number of Linear Attention Heads: 48 for V and 16 for QK
Head Dimension: 128
Gated Attention:
Number of Attention Heads: 24 for Q and 4 for KV
Head Dimension: 256
Rotary Position Embedding Dimension: 64
Feed Forward Network:
Intermediate Dimension: 17408
LM Output: 248320 (Padded)
MTP: trained with multi-steps
Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Benchmark Results
Language
Qwen3.5-27B
Qwen3.5-397B-A17B
Gemma4-31B
Claude 4.5 Opus
Qwen3.6-35B-A3B
Qwen3.6-27B
Coding Agent
SWE-bench Verified
75.0
76.2
52.0
80.9
73.4
77.2
SWE-bench Pro
51.2
50.9
35.7
57.1
49.5
53.5
SWE-bench Multilingual
69.3
69.3
51.7
77.5
67.2
71.3
Terminal-Bench 2.0
41.6
52.5
42.9
59.3
51.5
59.3
SkillsBench Avg5
27.2
30.0
23.6
45.3
28.7
48.2
QwenWebBench
1068
1186
1197
1536
1397
1487
NL2Repo
27.3
32.2
15.5
43.2
29.4
36.2
Claw-Eval Avg
64.3
70.7
48.5
76.6
68.7
72.4
Claw-Eval Pass^3
46.2
48.1
25.0
59.6
50.0
60.6
QwenClawBench
52.2
51.8
41.7
52.3
52.6
53.4
Knowledge
MMLU-Pro
86.1
87.8
85.2
89.5
85.2
86.2
MMLU-Redux
93.2
94.9
93.7
95.6
93.3
93.5
SuperGPQA
65.6
70.4
65.7
70.6
64.7
66.0
C-Eval
90.5
93.0
82.6
92.2
90.0
91.4
STEM & Reasoning
GPQA Diamond
85.5
88.4
84.3
87.0
86.0
87.8
HLE
24.3
28.7
19.5
30.8
21.4
24.0
LiveCodeBench v6
80.7
83.6
80.0
84.8
80.4
83.9
HMMT Feb 25
92.0
94.8
88.7
92.9
90.7
93.8
HMMT Nov 25
89.8
92.7
87.5
93.3
89.1
90.7
HMMT Feb 26
84.3
87.9
77.2
85.3
83.6
84.3
IMOAnswerBench
79.9
80.9
74.5
84.0
78.9
80.8
AIME26
92.6
93.3
89.2
95.1
92.7
94.1
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Vision Language
Qwen3.5-27B
Qwen3.5-397B-A17B
Gemma4-31B
Claude 4.5 Opus
Qwen3.6-35B-A3B
Qwen3.6-27B
STEM & Puzzle
MMMU
82.3
85.0
80.4
80.7
81.7
82.9
MMMU-Pro
75.0
79.0
76.9
70.6
75.3
75.8
MathVista mini
87.8
--
79.3
--
86.4
87.4
DynaMath
87.7
86.3
79.5
79.7
82.8
85.6
VlmsAreBlind
96.9
--
87.2
--
96.6
97.0
General VQA
RealWorldQA
83.7
83.9
72.3
77.0
85.3
84.1
MMStar
81.0
83.8
77.3
73.2
80.7
81.4
MMBenchEN-DEV-v1.1
92.6
--
90.9
--
92.8
92.3
SimpleVQA
56.0
67.1
52.9
65.7
58.9
56.1
Document Understanding
CharXiv RQ
79.5
80.8
67.9
68.5
78.0
78.4
CC-OCR
81.0
82.0
75.7
76.9
81.9
81.2
OCRBench
89.4
--
86.1
--
90.0
89.4
Spatial Intelligence
ERQA
60.5
67.5
57.5
46.8
61.8
62.5
CountBench
97.8
97.2
96.1
90.6
96.1
97.8
RefCOCO avg
90.9
92.3
--
--
92.0
92.5
EmbSpatialBench
84.5
--
--
--
84.3
84.6
RefSpatialBench
67.7
--
4.7
--
64.3
70.0
Video Understanding
VideoMME(w sub.)
87.0
87.5
--
77.7
86.6
87.7
VideoMMMU
82.3
84.7
81.6
84.4
83.7
84.4
MLVU
85.9
86.7
--
81.7
86.2
86.6
MVBench
74.6
77.6
--
67.2
74.6
75.5
Visual Agent
V*
93.7
95.8
--
67.0
90.1
94.7
AndroidWorld
64.2
--
--
--
--
70.3
* Empty cells (--) indicate scores not yet available or not applicable.
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks.
In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important]
Inference efficiency and throughput vary significantly across frameworks.
We recommend using the latest framework versions to ensure optimal performance and compatibility.
For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important]
The model has a default context length of 262,144 tokens.
If you encounter out-of-memory (OOM) errors, consider reducing the context window.
However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.
sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.
vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing.
For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
Please note that the support for sampling parameters varies according to inference frameworks.
[!Important]
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by <think>\n...</think>\n\n before producing the final responses.
To disable thinking content and obtain direct response, refer to the examples here.
1from openai import OpenAI
2# Configured by environment variables3client = OpenAI()45messages =[6{7"role":"user",8"content":[9{10"type":"image_url",11"image_url":{12"url":"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"13}14},15{16"type":"text",17"text":"The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"18}19]20}21]2223response = client.chat.completions.create(24 model="Qwen/Qwen3.6-27B",25 messages=messages,26 max_tokens=81920,27 temperature=1.0,28 top_p=0.95,29 presence_penalty=0.0,30 extra_body={31"top_k":20,32},33)34print("Chat response:", chat_response)
Video Input
python
1from openai import OpenAI
2# Configured by environment variables3client = OpenAI()45messages =[6{7"role":"user",8"content":[9{10"type":"video_url",11"video_url":{12"url":"https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"13}14},15{16"type":"text",17"text":"How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"18}19]20}21]2223# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,24# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).25# This feature is currently supported only in vLLM.26#27# By default, `fps=2` and `do_sample_frames=True`.28# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.29response = client.chat.completions.create(30 model="Qwen/Qwen3.6-27B",31 messages=messages,32 max_tokens=81920,33 temperature=1.0,34 top_p=0.95,35 presence_penalty=0.0,36 extra_body={37"top_k":20,38"mm_processor_kwargs":{"fps":2,"do_sample_frames":True},39},40)4142print("Chat response:", chat_response)
Instruct (or Non-Thinking) Mode
[!Important]
Qwen3.6 does not officially support the soft switch of Qwen3, i.e., /think and /nothink.
Qwen3.6 will think by default before response.
You can obtain direct response from the model without thinking by configuring the API parameters.
For example,
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "enable_thinking": False instead of "chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "preserve_thinking": True instead of "chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
python
1import os
2from qwen_agent.agents import Assistant
34# Define LLM5# Using Alibaba Cloud Model Studio6llm_cfg ={7# Use the OpenAI-compatible model service provided by DashScope:8'model':'qwen3.6-27b',9'model_type':'qwenvl_oai',10'model_server':'https://dashscope.aliyuncs.com/compatible-mode/v1',11'api_key': os.getenv('DASHSCOPE_API_KEY'),1213'generate_cfg':{14'use_raw_api':True,15# When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way16'extra_body':{17'enable_thinking':True,18'preserve_thinking':True,19},20},21}2223# Using OpenAI-compatible API endpoint.24# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.25#26# llm_cfg = {27# # Use your own model service compatible with OpenAI API by vLLM/SGLang:28# 'model': 'Qwen/Qwen3.6-27B',29# 'model_type': 'qwenvl_oai',30# 'model_server': 'http://localhost:8000/v1', # api_base31# 'api_key': 'EMPTY',32#33# 'generate_cfg': {34# 'use_raw_api': True,35# # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way36# 'extra_body': {37# 'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}38# },39# },40# }4142# Define Tools43tools =[44{'mcpServers':{# You can specify the MCP configuration file45"filesystem":{46"command":"npx",47"args":["-y","@modelcontextprotocol/server-filesystem","/Users/xxxx/Desktop"]48}49}50}51]5253# Define Agent54bot = Assistant(llm=llm_cfg, function_list=tools)5556# Streaming generation57messages =[{'role':'user','content':'Help me organize my desktop.'}]58for responses in bot.run(messages=messages):59pass60print(responses)6162# Streaming generation63messages =[{'role':'user','content':'Develop a dog website and save it on the desktop'}]64for responses in bot.run(messages=messages):65pass66print(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
Qwen3.6 natively supports context lengths of up to 262,144 tokens.
For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
Modifying the model configuration file:
In the config.json file, change the rope_parameters fields in text_config to:
[!NOTE]
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts.
We advise modifying the rope_parameters configuration only when processing long contexts is required.
It is also recommended to modify the factor as needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to set factor as 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
We suggest using the following sets of sampling parameters depending on the mode and task type:
Thinking mode for general tasks: temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
For supported frameworks, you can adjust the presence_penalty parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the answer field with only the choice letter, e.g., "answer": "C"."
Long Video Understanding: To optimize inference efficiency for plain text and images, the size parameter in the released video_preprocessor_config.json is conservatively configured. It is recommended to set the longest_edge parameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,
Q4_K_S (4-bit) ; non imatrix, standard default settings for Qwen 3.6 version model.
NOTES:
Some formatting lost on copy/paste ; original is flawless in terms of formatting, tables and charts.
Q4KS non-imatrix represents LOW end of the quality scale at 1/4 the precision of the full model.
Export of MTP generated content is broken in LMStudio (all formats)
PROMPT:
Explain 10 ways (in extensive detail) to use the "night" time cooling of radiant energy into space to reduce global temperatures. Include charts, and tables.
Thought
for 42.50 seconds
Here's
a thinking process:
Analyze
the Request:
Topic: Use
night-time cooling of radiant energy into space (radiative cooling)
to reduce global temperatures (geoengineering/climate mitigation).
Quantity: 10
ways.
Detail
Level: Extensive detail.
Requirements: Include
charts and tables.
Understand
the Core Science (Radiative Cooling):
What
is it? Objects emit thermal radiation (infrared) based on
their temperature. Earth loses heat this way at night (and day)
when it's cooler than the surroundings.
The
"Atmospheric Window": Between roughly 8 to 13
micrometers (μm), the atmosphere is relatively transparent. If an
object radiates primarily in this window, it can lose heat directly
to outer space (which is ~3K), even during the day if solar
absorption is blocked.
Key
principle for geoengineering: Enhance this process on a
massive scale, either by increasing the area of surfaces that
radiate efficiently, by changing the properties of surfaces
(emissivity/reflectivity), or by mechanically pumping coldness (or
heat) to where it can escape.
Brainstorming
the 10 Methods (Divergent Thinking):
Idea
1: Passive Radiative Cooling Surfaces (Buildings/Roofs). Using
new materials that reflect sun and emit in IR window. Huge surface
area.
Idea
2: Radiative Cooling Desalination/Cooling Plants. Using
radiative cooling to produce fresh water or chill water for
industrial cooling.
Idea
3: Space-based Radiators. Putting giant panels in orbit
to radiate Earth's excess heat. (Classic idea).
Idea
4: High-Altitude Balloons. Filling stratosphere with
radiative aerosols or particles (e.g., barium sulfate) that emit IR
but scatter little sun.
Idea
5: Oceanic Radiative Cooling. Floating films or particles
on the ocean surface to enhance IR escape.
Idea
6: Thermal Pumping to High Altitude. Using pumps to move
warm air/water to higher altitudes where IR escapes better.
Idea
7: Glacial Enhancement/Expansion. Expanding ice sheets or
glaciers (high albedo + radiative cooling) via artificial snow or
shading.
Idea
8: Subsurface Heat Exchange. Using deep earth cooling
(though this is more thermal storage), but maybe pumping heat to
surface at night to radiate? (A bit weak).
Idea
9: Radiative Cooling in Power Plant Cooling Towers. Modifying
cooling towers to radiate more efficiently at night and store cold.
Idea
10: "Cold" Waste Heat Rejection. Linking
urban/industrial waste heat to radiative cooling systems to dump
heat faster.
Refining
and Structuring the 10 Methods (for Extensive Detail):
I
need to focus on distinct mechanisms or applications.
Let's select and refine.
Method
1: Global Passive Radiative Cooling Infrastructure (Urban/Rural
Surfaces). Focus on metamaterials.
Method
2: Stratospheric Radiative Aerosol Injection (SRAI). Particles
specifically designed for high IR emissivity and low solar
scattering.
Method
3: Space-Based Radiator Arrays (SBRA). Giant panels in LEO or
GEO.
Method
4: Oceanic Surface Radiative Films. Polymers or particles
applied to the oceans.
Method
6: Thermal Pumping Systems (Heat-to-Space). Mechanical systems
moving heat to thin air.
Method
7: Cryogenic Radiative Cooling Desalination (CRCD). Combining
cooling, water production, and cold storage.
Method
8: Artificial Glacial Expansion (AGE). Expanding ice sheets to
increase both albedo and radiative cooling.
Method
9: Radiative Cooling Integrated Power Grids. Linking waste
heat to radiators.
Method
10: Planetary Albedo-IR Emissivity Modulation via Cloud Seeding.
Modifying clouds to be transparent to outgoing IR while reflecting
solar (hard but distinct).
Drafting
the Content (Iterative Process):
For
each method, I need:
Title
& Brief Overview.
Mechanism
(How it works physically).
Scale/Implementation
(How big, where).
Potential
Impact (Rough estimates, if known).
Challenges/Risks.
I'll
aim for ~500-700 words per method (in the final output, but I'll
keep it concise in my notes and expand later).
Developing
Charts and Tables:
Chart
1: Comparison of Potential Temperature Reduction (bar
chart).
Chart
2: Cost vs. Impact (scatter plot).
Table
1: Summary of 10 Methods (Key parameters).
Chart
3: Timeline of Implementation.
Execution
(Simulated Drafting - Mental Outline):
Intro:
Define radiative cooling, atmospheric window, potential for
geoengineering.
Method
10 (Cloud Seeding): Modify cloud microphysics to increase IR
transparency. Risky.
Charts/Tables:
Design them conceptually and then render them as ASCII or
structured markdown.
Conclusion:
Summary, risks, need for combination.
Refining
and Expanding (Adding "Extensive Detail"):
Technical
Depth: I'll need to discuss:
Stefan-Boltzmann
law (E = εσT^4)
Emissivity
(ε) vs. reflectivity (R) vs. transmissivity (T)
Atmospheric
window (8-13 μm)
Thermal
mass and heat capacity
Energy
balances
Specific
Examples:
For
Method 1: Mention specific materials (e.g., SiC, AlN, polymer
films).
For
Method 2: Mention particle size, optical properties.
For
Method 3: Mention size (km-scale), materials.
For
Method 4: Mention biodegradability, ocean current effects.
For
Method 5: Mention altitude (20-30 km), helium vs. hot air.
For
Method 6: Mention Carnot efficiency, heat exchangers.
For
Method 7: Mention latent heat of fusion, ice storage.
For
Method 8: Mention albedo feedback loops.
For
Method 9: Mention industrial waste heat temps.
For
Method 10: Mention cloud condensation nuclei.
Addressing
Potential Pitfalls/Errors:
Confusion
with Solar Geoengineering: I must be careful to
distinguish between reflecting sunlight (albedo modification) and
enhancing heat loss (radiative cooling). Some methods may have both
effects (e.g., glacial expansion), but the focus must be on the
radiative cooling component.
Energy
Balance: I need to ensure that the energy used to run a
system doesn't exceed the cooling benefit.
Feasibility: I'll
note that some methods are highly theoretical or expensive.
Constructing
the Final Output (Structure):
Title
Introduction
Method
1 - 10 (each with subsections)
Comparative
Analysis (Charts & Tables)
Conclusion
References
(if applicable, but I'll omit for brevity unless requested)
Self-Correction/Review
during Drafting:
Check: Did
I include 10 distinct methods? Yes.
Check: Is
the detail extensive? I'll ensure each method is well-developed.
Check: Are
there charts and tables? I'll create them as ASCII/markdown.
Check: Is
the science accurate? I'll review the physics of radiative cooling.
Check: Is
the tone appropriate? Technical and analytical.
Final
Polish (Mental Simulation of Output):
I'll
use clear headings, bullet points, and structured tables.
I'll
ensure the charts are readable in text form.
I'll
add a disclaimer that these are conceptual and require further
research.
Now,
I'll begin generating the content in detail.
OUTPUT:
Radiative
Geoengineering: 10 Methods to Use Night-Time Radiative Cooling to
Mitigate Global Warming
1.
Introduction
Global
warming is driven by an imbalance between incoming solar radiation
and outgoing terrestrial infrared radiation. Conventional
geoengineering approaches, such as solar radiation management (SRM)
or carbon dioxide removal (CDR), typically target either side of this
equation directly. However, a lesser-exploited mechanism—radiative
cooling—offers a pathway to enhance the Earth’s natural
ability to emit thermal energy directly into deep space.
The
Earth’s atmosphere contains a spectral "window" between
approximately 8 and 13 micrometers (μm), where it
is relatively transparent to infrared radiation. Objects that can
emit thermal radiation primarily within this window can lose heat
directly to the cosmic microwave background (~3 K), bypassing most
atmospheric greenhouse gases. This phenomenon, naturally occurring at
night when solar heating is absent, can be engineered on a global
scale to reduce planetary temperatures.
This
document outlines ten distinct, extensive methods
for leveraging night-time radiative cooling as a geoengineering tool.
Each method is analyzed for its physical mechanism, scalability,
implementation strategies, potential impact, and risks. Comparative
charts and tables are provided to facilitate cross-method evaluation.
2.
The Ten Methods
1.
Global Passive Radiative Cooling Infrastructure (PRCI)
A.
Mechanism
This
method involves coating vast urban and rural surfaces—roofs,
pavements, facades, and industrial structures—with engineered
materials that exhibit:
High
solar reflectivity (>90%): To minimize daytime heat
absorption.
High
infrared emissivity (ε > 0.9) in the 8–13 μm atmospheric
window: To maximize heat loss via thermal radiation.
Low
thermal mass: To enable rapid temperature swings between
day and night.
The
materials operate passively (no external energy input), relying
solely on the radiative imbalance. By increasing the effective
radiating surface area and emissivity, the system enhances night-time
heat loss, which can be partially stored in the ground or building
mass to reduce daytime temperatures.
B.
Scale and Implementation
Area
Target: 10–30 million km² (urban and industrial zones
globally).
Materials:
Polymer-based
films (e.g., ethylene-vinyl acetate, polyethylene).
Unlike
traditional SRM, which uses reflective particles (e.g., sulfate
aerosols) to scatter sunlight, SRAI introduces particles that are:
Transparent
or nearly transparent to visible and near-infrared solar radiation.
Highly
emissive in the mid-infrared (8–13 μm) atmospheric window.
These
particles act as artificial radiators in the stratosphere, where
atmospheric pressure is low and radiative escape is more efficient.
They emit heat directly into space, increasing the Earth’s
effective emissivity.
B.
Scale and Implementation
Particle
Types:
Barium
sulfate (BaSO₄)
Magnesium
oxide (MgO)
Carbon-based
nanoparticles with tailored emissivity.
Quantity:
10–50 million tons annually, dispersed via high-altitude aircraft
or balloons.
Altitude:
20–30 km, where residence time is months to years.
C.
Potential Impact
Estimated
Temperature Reduction: 0.2–0.5°C globally, depending on
particle concentration.
Time
to Effect: Months to one year.
D.
Challenges and Risks
Particle
Dynamics: Risk of unintended scattering if particle size or
shape is not tightly controlled.
Chemical
Interactions: Potential interactions with stratospheric
ozone or other chemicals.
Monitoring
and Control: Requires global monitoring to prevent uneven
cooling or atmospheric disturbances.
3.
Space-Based Radiator Arrays (SBRA)
A.
Mechanism
SBRA
involves deploying large arrays of radiative panels in low Earth
orbit (LEO) or geostationary orbit (GEO) designed to:
Absorb
Earth’s infrared radiation.
Re-emit
it into deep space, where it does not return to Earth.
These
panels would be constructed from materials with high emissivity in
the IR range and low reflectivity to solar radiation (or equipped
with sunshades). Unlike solar shades, SBRA enhances heat loss rather
than blocking incoming energy.
B.
Scale and Implementation
Array
Size: Each array could be 10–100 km in diameter; multiple
arrays required for global effect.
Materials:
Carbon
nanotube meshes.
Ceramic
composites with high thermal conductivity and emissivity.
Power
Source: Solar power for attitude control, maintenance, and
thermal management.
C.
Potential Impact
Estimated
Temperature Reduction: Up to 1.0–2.0°C globally,
depending on total array area.
Time
to Effect: Decades (due to construction and deployment
time).
D.
Challenges and Risks
Cost:
Extremely high, potentially trillions of dollars.
Debris
and Collisions: Risk of orbital debris generation and
satellite interference.
Political
and Legal Issues: Requires international agreements on
space use and control.
4.
Oceanic Surface Radiative Films (OSRF))
A.
Mechanism
OSRF
involves applying a thin, floating film across large portions of the
ocean surface to:
Increase
infrared emissivity in the 8–13 μm window.
Reduce
evaporation (which can otherwise lead to latent heat
loss but also cloud formation).
Enhance
night-time radiative cooling of the ocean surface
layer.
The
film would be hydrophobic, biodegradable, and capable of withstanding
waves and currents.
B.
Scale and Implementation
Area
Target: 50–100 million km² of ocean surface.
Materials:
Fluorocarbon-based
polymers.
Silica-based
nanoparticles.
Biopolymers
derived from marine organisms.
Application:
Ships or autonomous drones dispersing film in targeted regions.
C.
Potential Impact
Estimated
Temperature Reduction: 0.1–0.3°C globally.
Additional
Benefits: Reduced evaporation may improve water retention
in arid coastal regions.
D.
Challenges and Risks
Environmental
Impact: Potential harm to marine ecosystems if materials
are toxic or accumulate.
Persistence:
Need for controlled degradation to prevent long-term surface
coverage.
Wind
and Current Effects: Redistribution may alter intended
cooling zones.
5.
High-Altitude Radiative Balloon Fleets (HABF)
A.
Mechanism
HABF
deploys large, high-altitude balloons in the stratosphere that:
Carry
radiative panels designed to emit infrared radiation
into space.
Remain
stationary or drift in controlled patterns to maximize
radiative loss.
Operate
at altitudes where atmospheric opacity is low,
enhancing radiative efficiency.
The
balloons would be powered by solar panels during the day and equipped
with energy storage for night-time operation.
B.
Scale and Implementation
Number
of Balloons: 100,000–500,000.
Altitude:
20–40 km.
Panel
Materials: Lightweight composites with high IR emissivity.
Control
Systems: GPS, communication links, and propulsion for
position control.
C.
Potential Impact
Estimated
Temperature Reduction: 0.2–0.6°C globally.
Time
to Effect: 5–10 years.
D.
Challenges and Risks
Maintenance:
High failure rates due to extreme conditions; need for autonomous
repair or replacement.
Cost:
Moderate to high, depending on scalability.
Regulatory
Issues: Airspace regulations and international coordination
required.
6.
Thermal Pumping Systems (Heat-to-Space)
A.
Mechanism
This
method uses mechanical systems to:
Extract
heat from the surface (e.g., urban areas, industrial
processes) during the day.
Transfer
it to high altitudes (stratosphere or near-space)
where it can be radiated into space more efficiently.
Utilize
heat exchangers or compressors to elevate the thermal
energy’s effective temperature, enhancing radiative loss via the
Stefan-Boltzmann law (E = εσT⁴).
B.
Scale and Implementation
Energy
Input: Significant electrical or mechanical energy
required.
Estimated
Temperature Reduction: 0.2–1.0°C globally, depending on
ice expansion.
Time
to Effect: 5–20 years.
D.
Challenges and Risks
Energy
Intensity: High energy requirements for snowmaking and
cooling.
Ecological
Impact: Potential disruption of polar ecosystems and ocean
circulation.
Feedback
Loops: Albedo and radiative feedbacks may accelerate or
inhibit melt rates unpredictably.
9.
Radiative Cooling Integrated Power Grids (RCIPG)
A.
Mechanism
RCIPG
integrates radiative cooling systems directly into power generation
and distribution networks:
Waste
heat from thermal power plants, industrial processes,
and urban infrastructure is collected.
Radiative
coolers are used to dissipate this heat into space,
especially at night.
Cold
storage (e.g., ice, chilled water) is used to provide
cooling during the day, reducing peak energy demand.
B.
Scale and Implementation
Integration
Points: Power plants, data centers, industrial facilities.
Components:
Heat
exchangers.
Radiative
panels.
Storage
systems.
Control
Systems: Automated temperature and energy management.
C.
Potential Impact
Estimated
Temperature Reduction: 0.1–0.3°C globally.
Additional
Benefits: Improved efficiency of power generation and
reduced emissions.
D.
Challenges and Risks
Retrofit
Costs: High initial investment for existing facilities.
Energy
Balance: Must ensure net cooling benefit exceeds energy
used for operation.
Regulatory
Compliance: Adherence to environmental and safety
standards.
10.
Planetary Albedo-IR Emissivity Modulation via Cloud Seeding (PAEMCS)
A.
Mechanism
PAEMCS
modifies cloud properties to:
Increase
infrared transparency in the 8–13 μm window.
Maintain
or enhance solar reflectivity in the visible range.
Use
cloud condensation nuclei (CCN) or other agents to
alter droplet size, phase, and distribution.
By
tailoring cloud microphysics, this method aims to allow more outgoing
IR radiation to escape while still reflecting incoming sunlight,
effectively decoupling albedo and emissivity.
B.
Scale and Implementation
Target
Regions: Tropical and subtropical cloud formations.
Agents:
Sea
salt particles.
Sulfate
or nitrate aerosols.
Biogenic
particles.
Delivery
Systems: Aircraft, ships, or ground-based dispensers.
C.
Potential Impact
Estimated
Temperature Reduction: 0.1–0.5°C globally.
Time
to Effect: Weeks to months.
D.
Challenges and Risks
Complexity:
Cloud dynamics are highly complex and difficult to model accurately.
Unintended
Effects: Potential disruption of precipitation patterns,
storms, or monsoons.
Monitoring:
Requires extensive global observation systems.
3.
Comparative Analysis
3.1.
Summary Table of the 10 Methods
#
Method
Estimated Global Temp. Reduction (°C)
Cost (Relative)
Time to Effect
Scalability
Key Risk
1
PRCI
0.1–0.3
Low–Moderate
1–5 years
High
Material degradation
2
SRAI
0.2–0.5
Moderate
6–18 months
Moderate
Stratospheric chemistry
3
SBRA
1.0–2.0
Very High
20+ years
Low
Space debris, cost
4
OSRF
0.1–0.3
Low–Moderate
1–3 years
High
Marine ecosystem impact
5
HABF
0.2–0.6
Moderate–High
5–10 years
Moderate
Maintenance, regulatory
6
TPS
0.1–0.4
High
3–7 years
Moderate
Energy consumption
7
CRCD
0.05–0.2
Low
1–3 years
Low–Moderate
Location constraints
8
AGE
0.2–1.0
High
5–20 years
Moderate
Ecological disruption
9
RCIPG
0.1–0.3
Moderate
2–5 years
Moderate
Retrofit costs
10
PAEMCS
0.1–0.5
Moderate
3–12 months
Moderate
Weather disruption
3.2.
Chart: Potential Temperature Reduction by Method
Radiative
cooling offers a diverse set of tools for geoengineering that can
complement existing strategies for climate mitigation. The ten
methods outlined above range from passive, low-cost surface coatings
to complex, high-altitude and space-based systems. Each has distinct
advantages and challenges, requiring careful consideration of
scientific, economic, environmental, and political factors.
Key
Findings:
Passive
radiative cooling surfaces (PRCI) and stratospheric
radiative aerosols (SRAI) offer the most scalable and
cost-effective near-term options.
Space-based
radiators (SBRA) and high-altitude
balloons (HABF) provide higher potential impact but
require significant investment and technological development.
Oceanic
films (OSRF) and cryogenic desalination
(CRCD) offer dual benefits (e.g., water production)
but are constrained by geography and ecological considerations.
Artificial
glacial expansion (AGE) and cloud-seeding
modulation (PAEMCS) carry higher risks due to complex
feedbacks and potential unintended consequences.
Recommendations:
Pursue
a mixed strategy combining multiple
radiative cooling methods to balance risk and impact.
Invest
in research and development to improve
material properties, reduce costs, and enhance scalability.
Establish global
monitoring and governance frameworks to oversee
implementation and mitigate risks.
Radiative
cooling represents a promising, underexplored frontier in
geoengineering. With careful planning and international cooperation,
it could play a critical role in mitigating the effects of global
warming while providing ancillary benefits such as energy savings,
water production, and infrastructure resilience.